<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://jack-sears.github.io/blog/feed.xml" rel="self" type="application/atom+xml" /><link href="https://jack-sears.github.io/blog/" rel="alternate" type="text/html" /><updated>2026-07-28T17:34:09+00:00</updated><id>https://jack-sears.github.io/blog/feed.xml</id><title type="html">Jack’s Blog</title><subtitle>A blog where I post about the projects and ideas I have been working on relating to football analytics.</subtitle><entry><title type="html">The Quantification and Analysis of Second Balls in Football Part 2</title><link href="https://jack-sears.github.io/blog/notes/2026/07/26/analyzingSB.html" rel="alternate" type="text/html" title="The Quantification and Analysis of Second Balls in Football Part 2" /><published>2026-07-26T00:00:00+00:00</published><updated>2026-07-26T00:00:00+00:00</updated><id>https://jack-sears.github.io/blog/notes/2026/07/26/analyzingSB</id><content type="html" xml:base="https://jack-sears.github.io/blog/notes/2026/07/26/analyzingSB.html"><![CDATA[<p>In <a href="https://jack-sears.github.io/blog/notes/2026/06/19/quantifyingSB.html">part 1</a>, we looked into building upon <a href="https://lchunhang.medium.com/quantifying-second-ball-wins-d626ac56f108">Hang’s</a> framework for extracting second ball wins from data and incorporated our own ideas such as high-order balls to create player and team statistics and heatmaps. Feel free to give it a read but if you haven’t, all you need to know for this post is the two following points.</p>

<ul>
  <li>We have built the means to extract second balls from data.</li>
  <li>We look at the resulting possession following a second ball win, “the second ball possession”, which ends with a change in possession, stoppage in play, or a shot on target.</li>
</ul>

<p>Also, both the work done in part 1 and 2, have been taken directly from my master’s thesis. I just have shortened it significantly into (hopefully) a quicker and easier read. There’s a much deeper analysis into the accuracy of every component in the model. Feel free to take a look <a href="https://ontariotechu.scholaris.ca/items/a899d89d-bfc1-4ce0-b2f3-2c1e36bf6742">here</a>.</p>

<p>The goal of this work, is to create a methodology to give insight into the value of second ball wins, beyond just the number and location of them that occur. We do this by predicting where they occur and the attacking value they add to the second ball winning team.</p>

<p>On that note, let’s get into the model and analysis.</p>

<h2 id="model-overview">Model Overview</h2>

<p>A model is created to estimate the attacking value from winning a second ball. It is called Expected Second Ball Value (xSBV) and is split into three components.</p>
<ol>
  <li>Location Prediction: where the ball is most likely to land.</li>
  <li>Win Probability: probability each team will win a second ball.</li>
  <li>Gain Difference: probability of scoring from a second ball win</li>
</ol>

<p>And the model can be described below:</p>

\[\text{xSBV} = \underbrace{P(L)}_{\text{Location Probability}} \times \underbrace{P(W \mid L, \mathbf{X})}_{\text{Win Probability}} \times \underbrace{\Delta_{i,j}P(G_H \mid W)}_{\text{Gain Difference}}\]

<p>where:</p>

<ul>
  <li>$L$ is the predicted location of the second ball,</li>
  <li>$W$ denotes the winning team (binary outcome: $W = 1$ for Team A, $W = 0$ for Team B),</li>
  <li>$\mathbf{X}$ represents contextual features (e.g., player positions, duel type),</li>
  <li>$\Delta_{i,j}P(G_H \mid W)$ is the difference in probability of a goal occurring within H transitions after a second ball win, $W$, from location $i$ to $j$.</li>
</ul>

<h3 id="pitch-discretization">Pitch Discretization</h3>

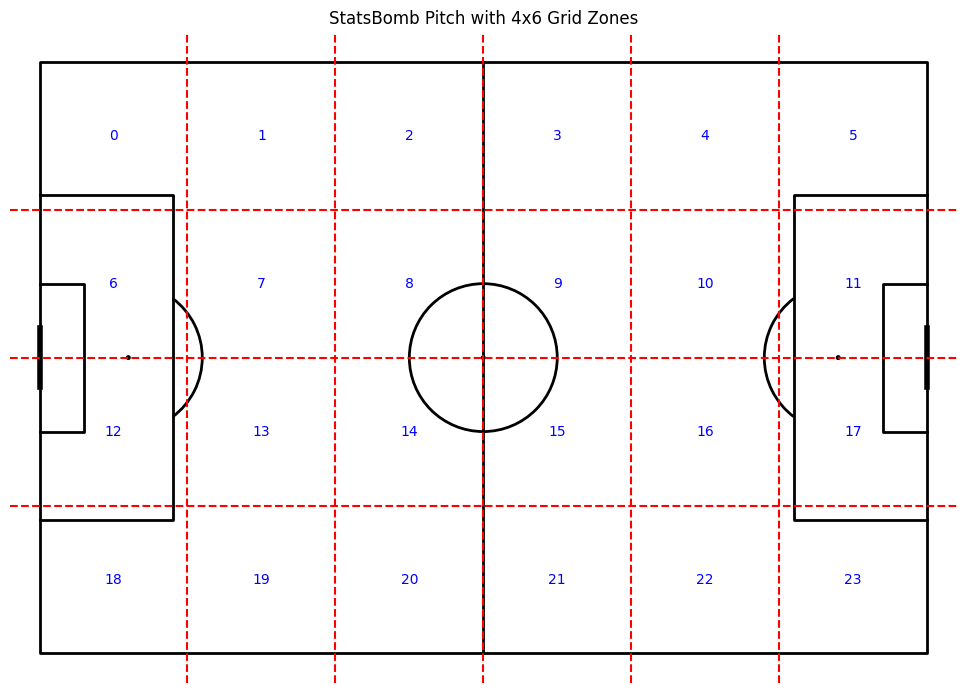
<p>To simplify modelling, the pitch is partitioned into a 4x6 grid. Using this grid we can get meaningful distinction between defensive, midfield, and attacking areas, as well as central and wide.</p>

<p><img src="https://jack-sears.github.io/blog/assets/images/pitch_discretized.png" alt="Pitch Discretization" /></p>

<h3 id="data-set-and-visualizaton">Data Set and Visualizaton</h3>

<p>For the following analysis I use event data from the 2015/2016 English Premier League which can be found <a href="https://github.com/statsbomb/open-data">here</a>, the StatsBomb open data github repo. It is event data and although tracking data would most likely improve the results of this work, the StatsBomb repo is all I had access too.</p>

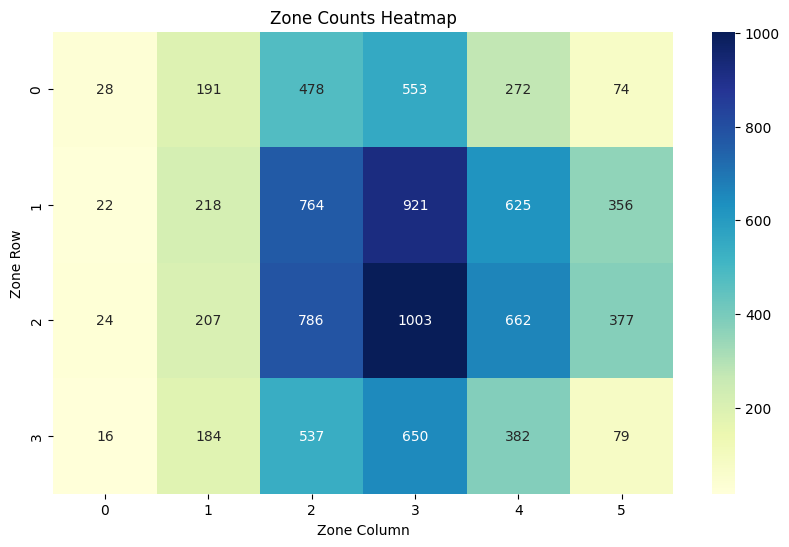
<p>The distribution of second balls and where they occur can provide us with some insight about characteristics of second balls.</p>

<p><img src="https://jack-sears.github.io/blog/assets/images/second_ball_hm.png" alt="sb heatmap" /></p>

<ol>
  <li>Second balls in the defensive third are low when compared to other thirds.</li>
  <li>The middle third dominates the locations of second balls.</li>
  <li>Second balls are less likely to occur in wide areas.</li>
</ol>

<h3 id="features">Features</h3>

<p>Thirteen features were created to capture the spatial and contextual dynamics of second balls. These components were taken from the event  data</p>

<table>
  <thead>
    <tr>
      <th>Feature Name</th>
      <th>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>pass_start_x, pass_start_y</td>
      <td>x and y coordinates of the starting location of the initial long ball.</td>
    </tr>
    <tr>
      <td>pass_end_x, pass_end_y</td>
      <td>x and y coordinates of the ending location of the initial long ball.</td>
    </tr>
    <tr>
      <td>pass_distance</td>
      <td>Length of the initial long ball.</td>
    </tr>
    <tr>
      <td>pass_angle</td>
      <td>Angle in radians of the initial long ball to the goal.</td>
    </tr>
    <tr>
      <td>dx, dy</td>
      <td>Change in x and y coordinates of the start and end location of the initial long ball.</td>
    </tr>
    <tr>
      <td>dist_to_centre</td>
      <td>Distance of the end location of the initial long ball to the centre of the field.</td>
    </tr>
    <tr>
      <td>is_defensive, is_midfield, is_attacking</td>
      <td>Boolean flags to indicate what third of the field the end location of the long ball occurs in.</td>
    </tr>
    <tr>
      <td>is_contested</td>
      <td>Boolean flag to indicate if the initial long ball is met with a duel, e.g. ADBA, ADAA, ADAB, or ADBB (see <a href="https://jack-sears.github.io/blog/notes/2026/06/19/quantifyingSB.html">previous post</a>).</td>
    </tr>
    <tr>
      <td>second_x, second_y</td>
      <td>x and y coordinates of the second ball location.</td>
    </tr>
    <tr>
      <td>has_transition</td>
      <td>Boolean flag to indicate if there is a transition period in the second ball win or not.</td>
    </tr>
  </tbody>
</table>

<h2 id="location-prediction">Location Prediction</h2>

<p><strong>Objective:</strong> Predict the zonal location of where a second ball occurs given a list of features.</p>

<h3 id="model-formulation">Model Formulation</h3>

<p>Let $p_0$ be the initial duel location and $X_{context}$ be a list of features. The second ball location, $L$, is modelled as a stochastic outcome:</p>

\[P(L_z \mid p_0, X_{context})\]

<p>where $L_z$ is the corresponding zone that location $L$ belongs to and</p>

\[\begin{aligned}
X_{context} = \{&amp;\text{pass_start_x, pass_start_y, pass_distance, pass_angle,} \\
&amp;\text{dx, dy, dist_to_centre, is_defensive, is_midfield,} \\
&amp;\text{is_attacking, is_contested}\}
\end{aligned}\]

<h3 id="modelling-techniques">Modelling Techniques</h3>

<p>The location prediction task is a multi-class classification problem <a href="https://www.appliedaicourse.com/blog/multiclass-classification-in-machine-learning/">(Singh, 2024)</a>, where the goal is to predict the pitch zone where the ball is most likely to land after a contested aerial action or clearance. Each instance is assigned a class label based on the observed ball destination. To model this, Extreme Gradient Boosting (XGBoost), a powerful gradient-boosted decision tree algorithm <a href="https://dl.acm.org/doi/10.1145/2939672.2939785">(Chen &amp; Guestrin, 2016)</a> is used. Due to the multi-class nature of the task, the model is trained using softmax objective with log-loss as the optimization criterion. Model performance is evaluated using top-k accuracy metrics <a href="https://www.sciencedirect.com/science/article/abs/pii/S0031320325000019">(Ghosh et al., 2025)</a>, specifically top-1 and top-3, to assess how often the true location falls within the top predicted zones.</p>

<h2 id="second-ball-winning-team-prediction">Second Ball Winning Team Prediction</h2>

<p><strong>Objective:</strong> Estimate the probability that a given team wins the second ball at location L.</p>

<h3 id="model-formulation-1">Model Formulation</h3>

<p>A binary classifier predicts:</p>

\[P(W = Team_A \mid L, X_{context})\]

<p>where $W$ denotes a second ball win and</p>

\[\begin{aligned}
X_{context} = \{&amp;\text{pass_start_x, pass_start_y, pass_distance, pass_angle,} \\
&amp;\text{dist_to_centre, is_defensive, is_midfield, is_attacking,} \\
&amp;\text{is_contested, second_x, second_y, has_transition}\}
\end{aligned}\]

<h3 id="modelling-techniques-1">Modelling Techniques</h3>

<p>The task of predicting which team will win a second ball is formulated as a binary classification problem <a href="https://www.learndatasci.com/glossary/binary-classification/">(Karabiber, n.d)</a>, where the model must determine whether the team initiating the long ball or the opposing team will gain possession following the contest. Three machine learning models are used to address this problem: XGBoost, Random Forest, and Logistic Regression. Random Forest is an ensemble method that combines multiple decision trees to reach a single result, offering resistance to overfitting, especially when the feature space is large and noisy <a href="https://arxiv.org/abs/1511.05741">(Biau &amp; Scornet, 2016)</a>. Logistic Regression provides a simple and interpretable model, relying on a linear combination of input features passed through a sigmoid function to estimate the probability of each class <a href="https://www.geeksforgeeks.org/machine-learning/understanding-logistic-regression/">(GeeksforGeeks, 2016)</a>. Comparing these models allows for an evaluation of accuracy between different models.</p>

<h2 id="gain">Gain</h2>

<p>To quantify the probability that a goal occurs in the possession after a second ball win, a Markov chain model called gain is proposed. This approach is similar to <a href="https://nessis.org/nessis11/rudd.pdf">(Rudd, 2011)</a>, <a href="https://karun.in/blog/expected-threat.html">(Singh, 2018)</a>, and <a href="https://www.sloansportsconference.com/research-papers/decomposing-the-immeasurable-sport-a-deep-learning-expected-possession-value-framework-for-soccer">(Fernandez et al., 2019)</a>, but adjusted to my problem, which captures both immediate and transitional danger of second balls. This is basically my attempt at implementing expected threat.</p>

<h3 id="markov-chains-for-possession-transitions">Markov Chains for Possession Transitions</h3>

<p>A Markov chain is a probabilistic model that represents a system transitioning between discrete states, where the probability of moving to the next state depends only on the current state and not the sequence of events that precedes it <a href="https://math.libretexts.org/Bookshelves/Applied_Mathematics/Applied_Finite_Mathematics_%28Sekhon_and_Bloom%29/10%3A_Markov_Chains/10.01%3A_Introduction_to_Markov_Chains">(Sekhon &amp; Bloom, 2020)</a>. The assumption that the next state depends only on the current state, known as the Markov property, is a simplification that enables efficient modelling of second ball possessions. In reality, past actions may influence future outcomes, but this assumption is reasonable in a football context. For instance, there are many ways a team might advance the ball into the attacking third. However, once the ball is in the attacking third, the likelihood of scoring or losing possession is mainly determined by the current position and state of play, rather than the actions that led there. Absorbing states are such that once transitioned into, they cannot be left. In my context, there are two absorbing states: a goal and the end-of-possession. Transitions represent the movement of the ball between states. A transition matrix is constructed using observed transitions from the data, and convergence is used to estimate the long-term trends of the absorbing states. Below is the transition matrix.</p>

\[P = \begin{bmatrix}
p_{z_0, z_0} &amp; p_{z_0, z_1} &amp; \cdots &amp; p_{z_0, z_{23}} &amp; p_{z_0, z_g} &amp; p_{z_0, z_{eop}} \\
p_{z_1, z_0} &amp; p_{z_1, z_1} &amp; \cdots &amp; p_{z_1, z_{23}} &amp; p_{z_1, z_g} &amp; p_{z_1, z_{eop}} \\
\vdots &amp; \vdots &amp; \ddots &amp; \vdots &amp; \vdots &amp; \vdots \\
p_{z_{23}, z_0} &amp; p_{z_{23}, z_1} &amp; \cdots &amp; p_{z_{23}, z_{23}} &amp; p_{z_{23}, z_g} &amp; p_{z_{23}, z_{eop}} \\
0 &amp; 0 &amp; \cdots &amp; 0 &amp; 1 &amp; 0 \\
0 &amp; 0 &amp; \cdots &amp; 0 &amp; 0 &amp; 1
\end{bmatrix}\]

<p>The Markov chain framework is well-suited to this problem due to its interpretability, simplicity, and ability to capture the stochastic nature of ball progression in football. Formally, the possession evolution is modelled as a Markov process where:</p>

<ul>
  <li><strong>Transient States</strong>: The 24 grid zones ${z_1, \ldots, z_{24}}$</li>
  <li><strong>Absorbing States</strong>: Goal and End-of-Possession ${z_g, z_{eop}}$</li>
  <li><strong>Transitions</strong>: Probabilities $P(z_j \mid z_i, W)$ are estimated from historical data, conditioned on the winning team $W$.</li>
</ul>

<h3 id="convergence-of-the-transition-matrix">Convergence of the Transition Matrix</h3>

<p>Each multiplication of the transition matrix $P$ by itself represents an additional step in the possession sequence. Specifically, $P^n$ describes the probabilities of reaching any given state after $n$ transitions <a href="https://iopscience.iop.org/article/10.1088/1757-899X/335/1/012046">(Permana et al., 2018)</a>. For second ball possessions, the probability of a possession eventually reaching one of the absorbing states is of interest. By repeatedly multiplying the matrix by itself, these probabilities change and eventually stabilize. This process is known as <em>convergence</em>. In practice, the matrix is repeatedly multiplied by itself until there is a small enough state difference between iterations. The difference threshold value is arbitrarily chosen, and in this work 0.025 is used. Convergence allows for the long-term distribution of second ball possessions to be determined.</p>

<h3 id="model-formulation-2">Model Formulation</h3>

<h4 id="horizon-limited-markov-chain">Horizon-Limited Markov Chain</h4>

<p>Let $\mathbf{P_t} \in \mathbb{R}^{24 \times 24}$ denote the probability transition matrix between transient states, and let $\mathbf{P_g} \in \mathbb{R}^{24 \times 1}$ denote the column vector of transition probabilities from each transient state into the absorbing state “Goal”. For a fixed horizon $H$, the cumulative probability of absorption in the Goal state within $H$ steps, or <em>gain</em>, is</p>

\[P(G_H) = \left(\sum_{h=1}^{H} P_t^h\right) P_g \tag{3.6}\]

<p>Where:</p>

<ul>
  <li>$\mathbf{P_t^h}$ gives the distribution of transient states after exactly $h$ steps.</li>
  <li>multiplying by $\mathbf{P_g}$ projects these distributions onto the probability of transitioning to Goal.</li>
  <li>summing over $h$ accounts for scoring at any step up to horizon $H$.</li>
</ul>

<h4 id="gain-difference">Gain Difference</h4>

<p>The <em>gain difference</em> $\Delta_{i,j}P(G_H)$ is defined as the difference between the cumulative probability of scoring a goal within $H$ steps of zones:</p>

\[\Delta_{i,j}P(G_H) = P(G_H)[j] - P(G_H)[i] \tag{3.7}\]

<p>where $P(G_H)[n]$ is the $n$th element of $P(G_H)$, i.e., the probability of scoring within $H$ steps when starting in zone $z_n$.</p>

<h4 id="expected-gain">Expected Gain</h4>

<p>Let $\mathbf{P_{first}} \in \mathbb{R}^{24 \times 24}$ be the empirical distribution of the <em>first successful team action</em> destination conditioned on the start zone. Multiplying the first-action matrix with the expected scoring value and then subtracting the probability of scoring in $H$ steps from starting zone $z_i$ gives the expected gain for the first action following a second ball win.</p>

\[xP(G_H, z_i) = P_{first} P(G_H) - P(G_H)[i] \tag{3.8}\]

<p>Comparing expected gain to the actual gain players receive from second ball wins provides insight into which players underperform or overperform relative to expectations. Due to time constraints, I didn’t implement this in my work, but is a natural extension.</p>

<h2 id="component-performance">Component Performance</h2>

<p>After training the components using the above methodology, we evaluate the accuracy and performance of each.</p>

<h3 id="location-prediction-1">Location Prediction</h3>

<p>Rather than relying solely on the top-1 predicted location for second balls, this work
adopts a top-3 prediction strategy. In the context of football, the landing zone of a second
ball is uncertain due to seemingly chaotic nature. By considering the three most probable zones, a
more realistic representation of how the model is thinking and where it is predicting the
second balls to land is captured. Additionally, top-3 evaluation reduces the harshness
of strict classification accuracy and better reflects the model’s value in practical settings
where anticipating a region, rather than a single zone, can inform decision-making.</p>

<table>
  <thead>
    <tr>
      <th>Model</th>
      <th>Top-1 Accuracy</th>
      <th>Top-3 Accuracy</th>
      <th>Log Loss</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>XGBoost</td>
      <td>0.2382</td>
      <td>0.6022</td>
      <td>2.6712</td>
    </tr>
    <tr>
      <td>Naive Baseline</td>
      <td>0.1063</td>
      <td>0.2849</td>
      <td>-</td>
    </tr>
  </tbody>
</table>

<p>The location prediction component achieved a 23.8% top-1 and
60.2% top-3 accuracy. While these numbers indicate low prediction accuracy, they are notable given the complexity and novelty of the task. A naive baseline approach, simply predicting the most common zones, only has an accuracy of 10.6% top-1 and 28.5% top-3 accuracy. Significantly outperforming the naive baseline suggests the model is not random and has some ability to learn spatial patterns. Despite room for improvement, these results mark an important result in quantifying and modelling second ball outcomes in football.</p>

<h3 id="winning-team-prediction">Winning Team Prediction</h3>

<p>To evaluate the performance of the team winning prediction component, three core metrics are reported: accuracy, log loss, and the area under the receiver operating characteristic curve (AUC-ROC). AUC-ROC offers a more nuanced evaluation by measuring the
model’s ability to distinguish between positive and negative classes <a href="https://link.springer.com/chapter/10.1007/978-3-031-35314-7_2">(Naidu et al., 2023)</a>. An AUC-ROC
score of 0.5 indicates random performance, whereas a score closer to 1.0 reflects strong
discriminatory power. Log loss and accuracy are once again included to further help
analyze the model performance.</p>

<table>
  <thead>
    <tr>
      <th>Model</th>
      <th>Accuracy</th>
      <th>AUC-ROC Score</th>
      <th>Log Loss</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Logistic Regression</td>
      <td>0.704</td>
      <td>0.761</td>
      <td>0.584</td>
    </tr>
    <tr>
      <td>Random Forest</td>
      <td>0.718</td>
      <td>0.790</td>
      <td>0.554</td>
    </tr>
    <tr>
      <td>XGBoost</td>
      <td>0.722</td>
      <td>0.799</td>
      <td>0.548</td>
    </tr>
    <tr>
      <td>Naive Baseline</td>
      <td>0.585</td>
      <td>0.5</td>
      <td>-</td>
    </tr>
  </tbody>
</table>

<p>In the table above, it is shown that although all three models perform similarly, XGBoost is marginally the best. It is more important that the naive
baseline of always predicting team B as the winner of the second ball is outperformed.
With a slightly imbalanced dataset, predicting team B every time results in an accuracy
of 0.585, significantly lower than the best accuracy of 0.722. Another important note is
the AUC-ROC scores of the final models. All models are upwards of 0.75, with the best
being 0.799. These scores provide a good indication that the models are reliable and
meaningfully confident at discerning between winning and losing outcomes</p>

<h3 id="gain-1">Gain</h3>

<h4 id="visualizing-convergence">Visualizing Convergence</h4>

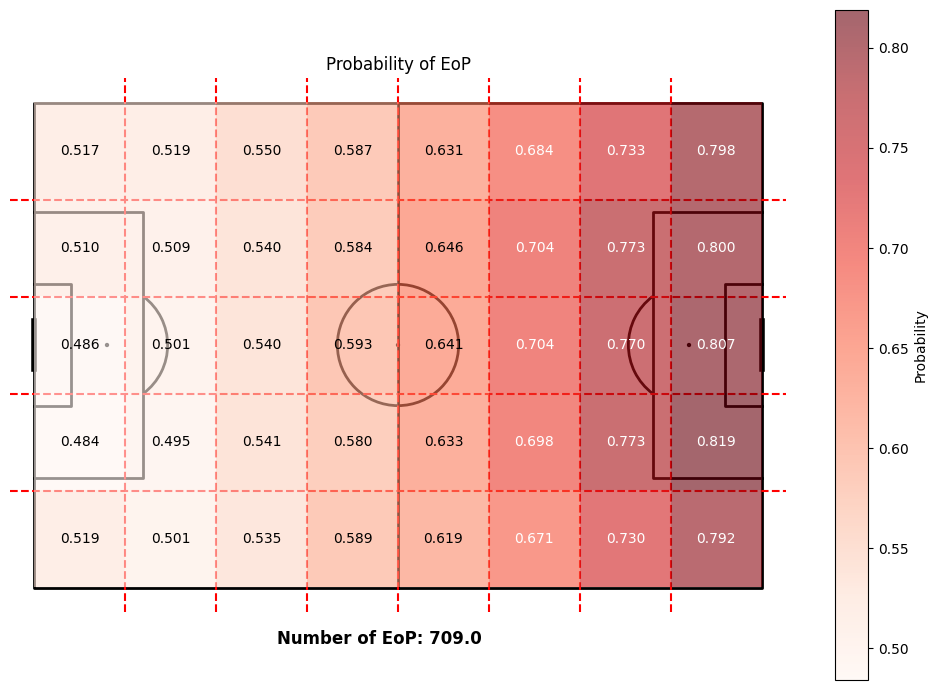
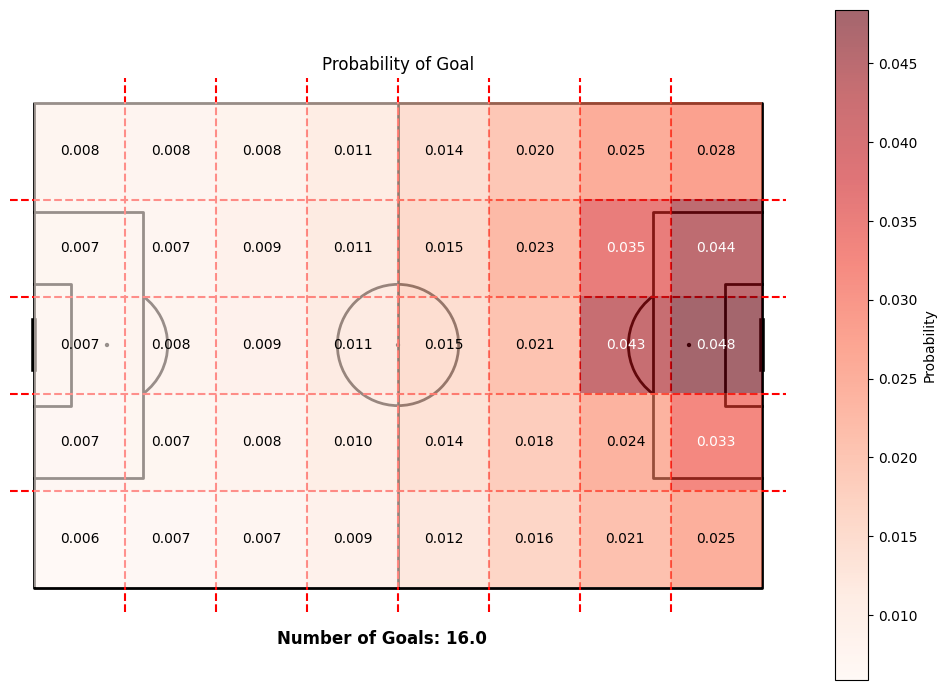
<p>To get an intuition for how the long-term distribution of second ball possessions emerge,
the heat maps of the absorbing states can be observed. The figures below shows the probability
of the possession ending after 20 transitions. There is a clear pattern that the closer the
team in possession gets to the opponent’s goal, the more likely the possession will end.
Again, this is trivial, but now we have evidence to back up the claim. The figures also
show the probability of a goal after 20 transitions. Again, there is a clear pattern that
the closer the team in possession gets to the opponent’s goal, the more likely they are to
score.</p>

<p><img src="https://jack-sears.github.io/blog/assets/images/eop_prob.png" alt="eop_heatmap" />
<img src="https://jack-sears.github.io/blog/assets/images/goal_prob.png" alt="goal_heatmap" /></p>

<h4 id="zone-valuation">Zone Valuation</h4>

<p>Visualizing the gain per zone can provide insight into how areas of the pitch are valued.
Unless otherwise stated, the analysis will be conducted using H = 5 (goal of occurring in next 5 transitions).</p>

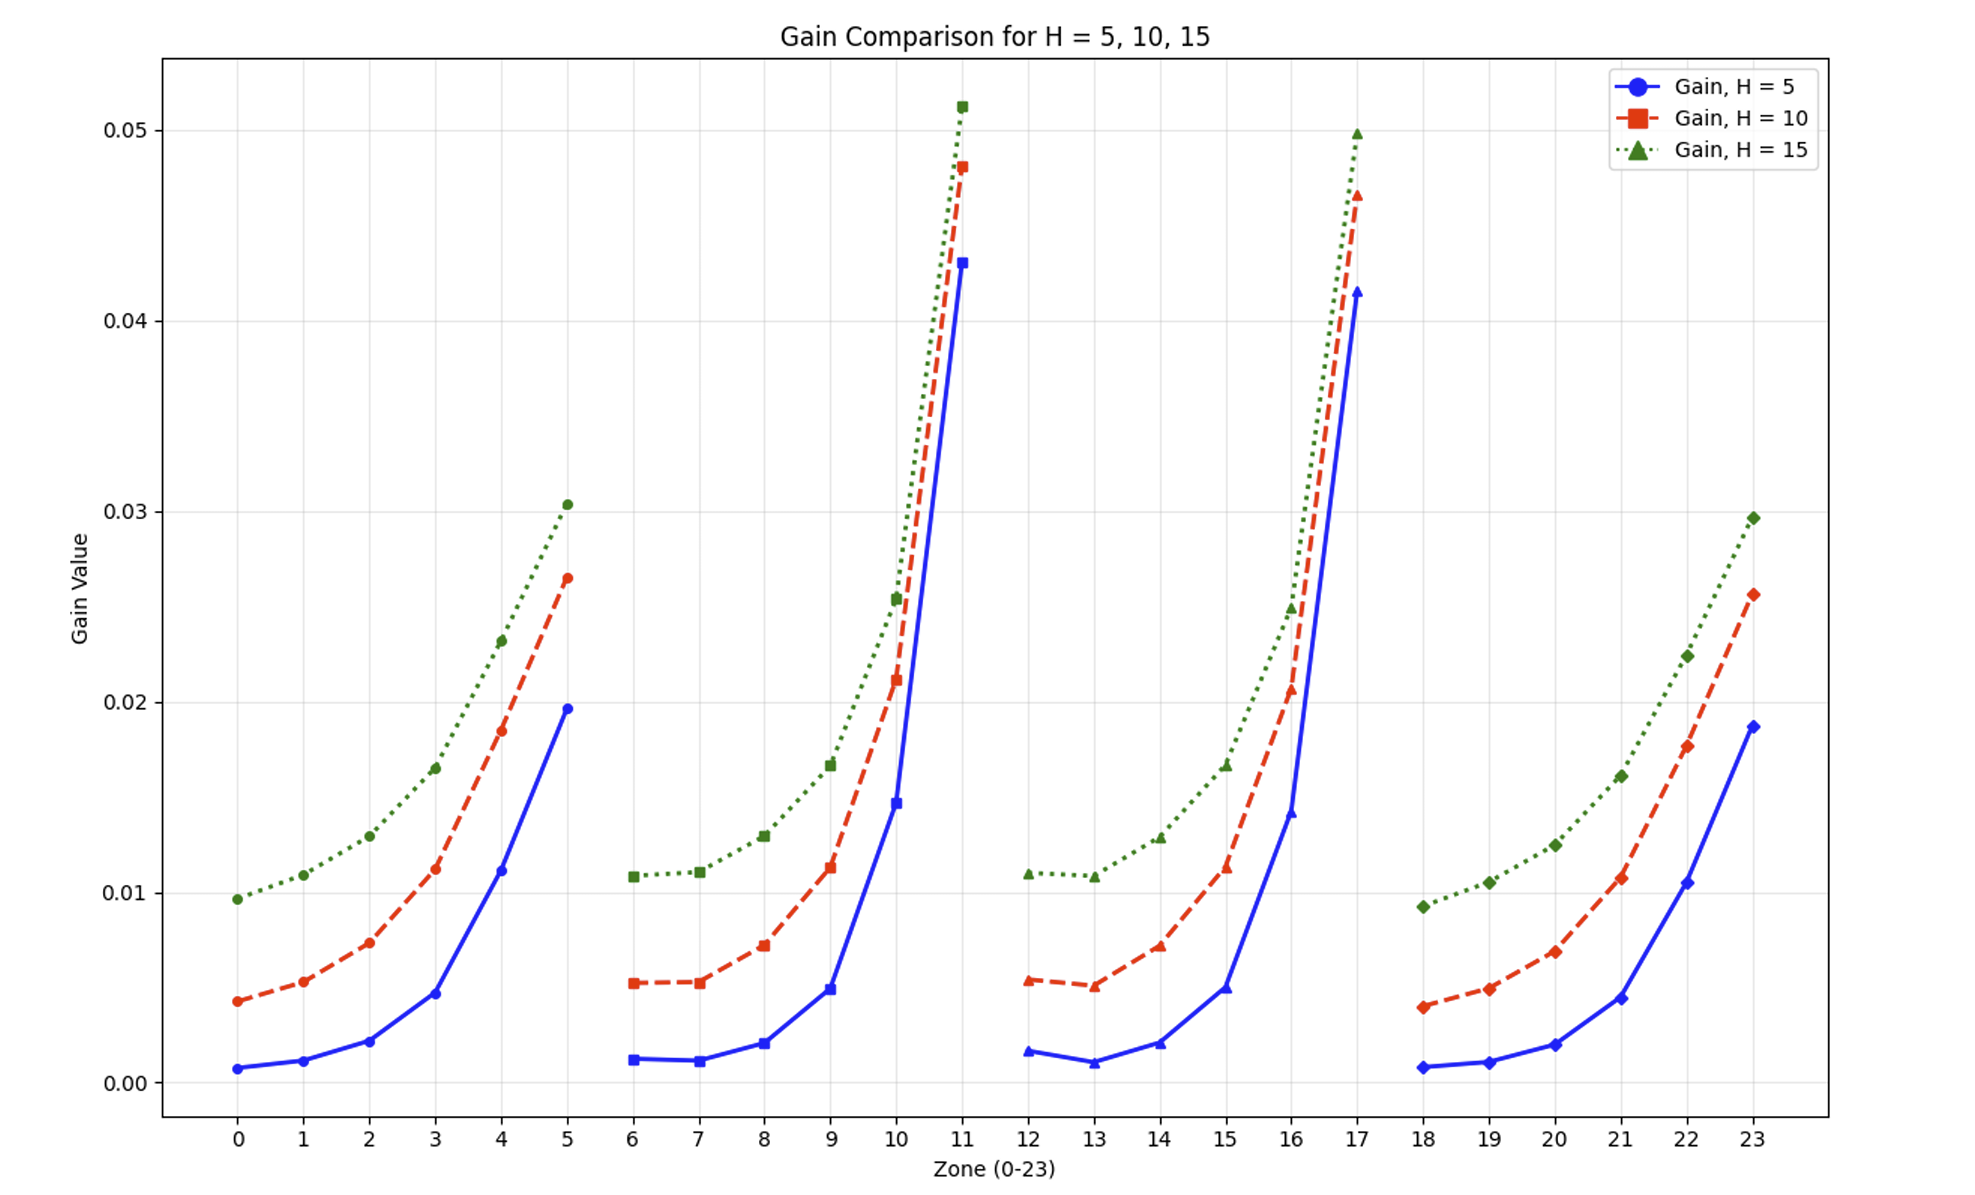
<p><img src="https://jack-sears.github.io/blog/assets/images/gain.png" alt="gain" /></p>

<p>As expected, the cumulative probability that a goal occurs in the next H actions
increases as H increases. Similarly to the convergence probabilities, we see that for H = 5, 10, 15, the closer
and narrower a player is to the opponent’s goal the more likely a goal will occur.</p>

<h4 id="bootstrapping">Bootstrapping</h4>

<p>To quantify the uncertainty in the gain component, the bootstrap, a resampling technique, is used. Bootstrapping uses an observed sample to construct a statistic’s sampling
distribution <a href="https://psycnet.apa.org/record/2011-23864-022">(Beasley &amp; Rodgers, 2012)</a>. The observed median from the original sample of N scores is calculated.
An empirical sampling distribution is created by repeatedly drawing N random samples
with replacement from the dataset of second ball possessions. Drawing N random samples is considered one bootstrap sample. This process is repeated B = 1000 times. The bootstrap distribution is formed by calculating the median for each bootstrap sample.</p>

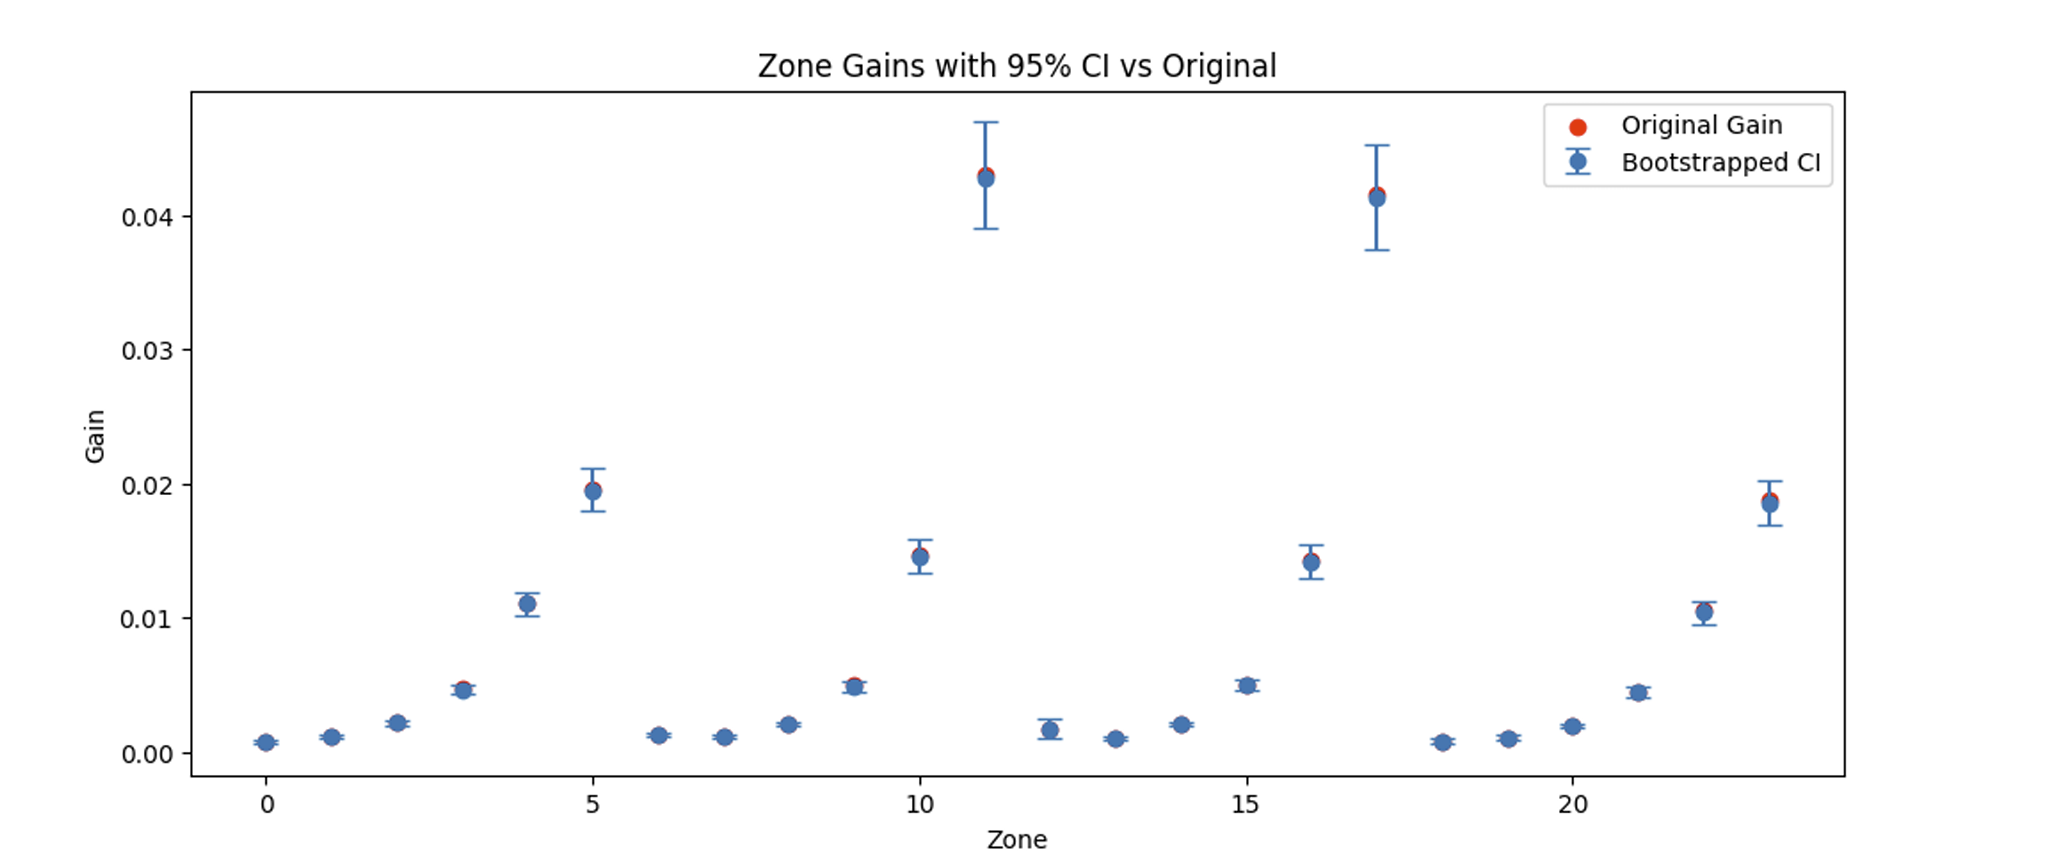
<p><img src="https://jack-sears.github.io/blog/assets/images/bootstrap.png" alt="bootstrap" /></p>

<p>From the above figure, it is clear that the original gain scores are very similar to the bootstrapped medians. Confidence intervals are minimal from defensive zones and appear to
grow towards attacking zones. Having more uncertainty in attacking zones is not surprising since there are fewer samples. However, the attacking zones’ confidence intervals
are not large, which gives evidence that the bootstrapped gain distribution is valid.</p>

<h4 id="calibration">Calibration</h4>

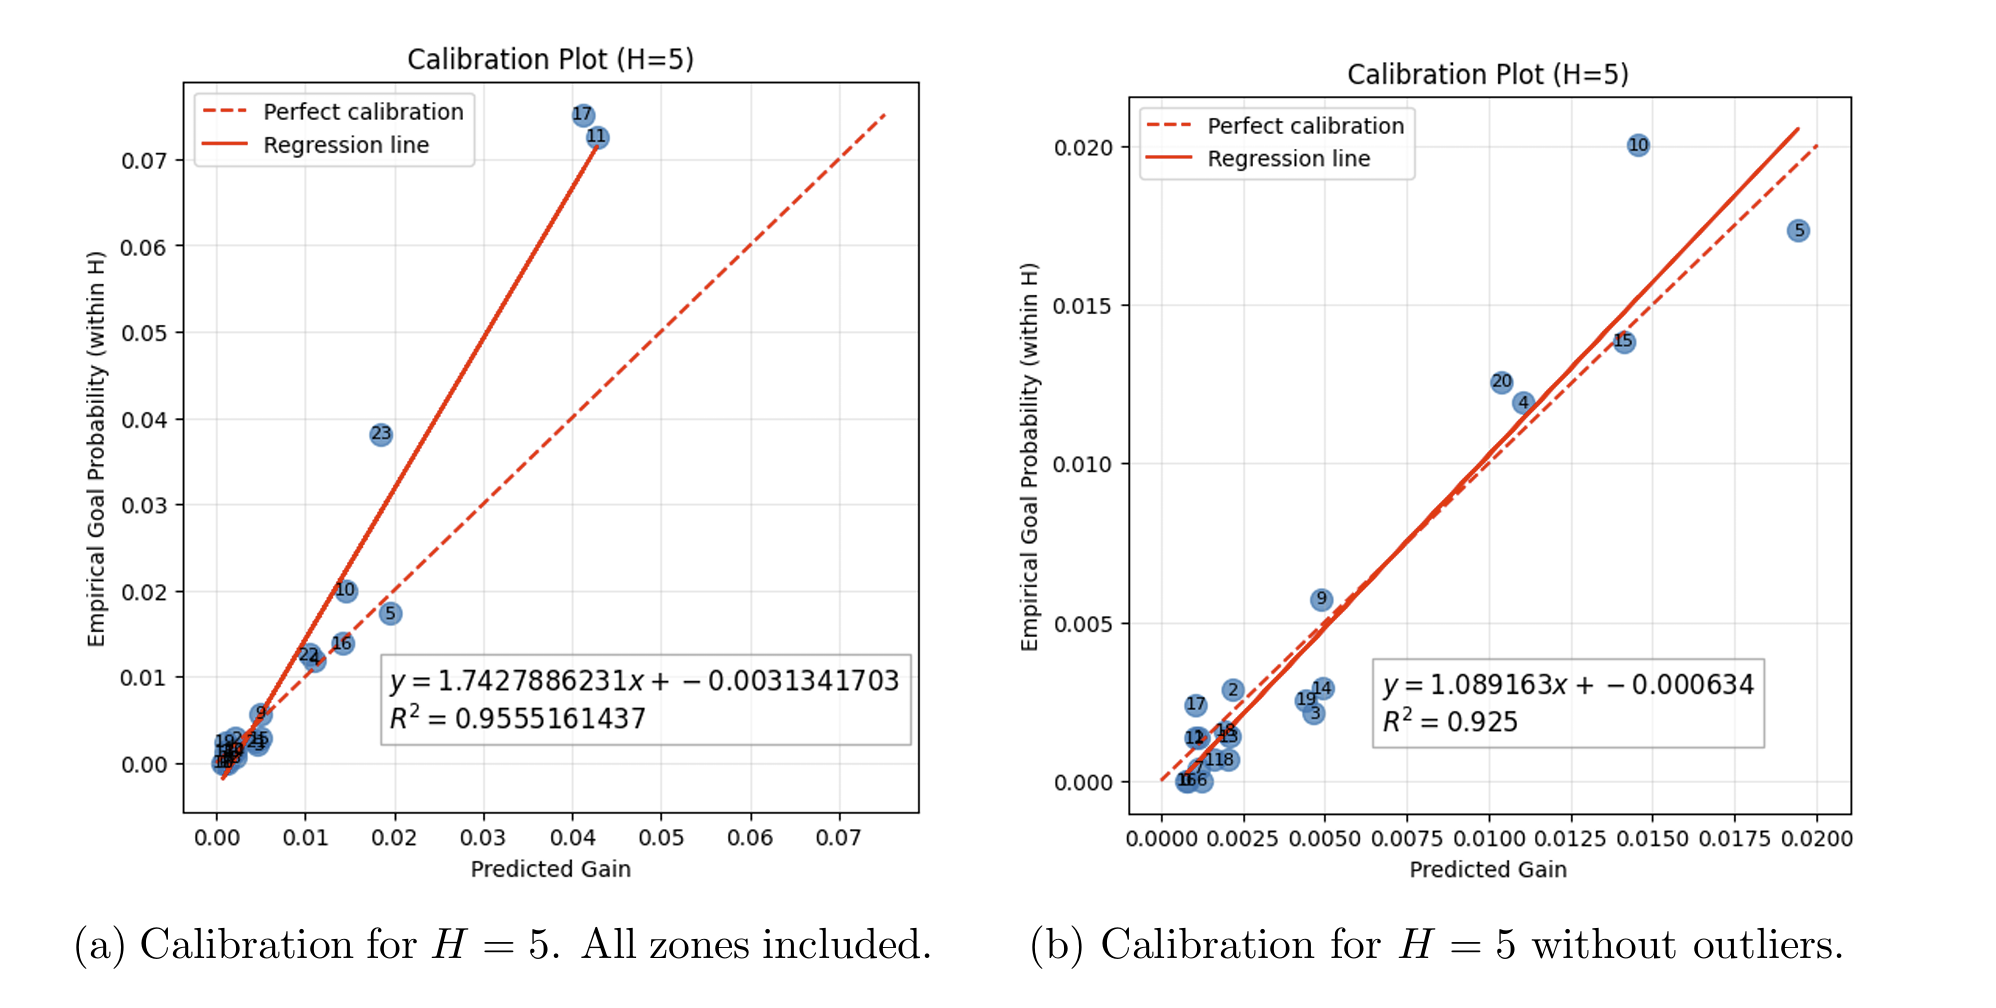
<p>The calibration of the gain was assessed by plotting empirical probabilities against predicted probabilities. The initial regression slope of approximately 1.7 indicates calibration issues compared to the perfect calibration slope of 1. Excluding zones 11, 17, and
23 decreases the slope to 1.089, which is very strong. The outliers have low empirical
counts since they are attacking zones, suggesting the empirical probability does not reflect the underlying gain distribution. However, for the majority of zones, the Markov
chain framework produces well-calibrated estimates.</p>

<p><img src="https://jack-sears.github.io/blog/assets/images/calibration.png" alt="calibration" /></p>

<h2 id="player-analysis">Player Analysis</h2>

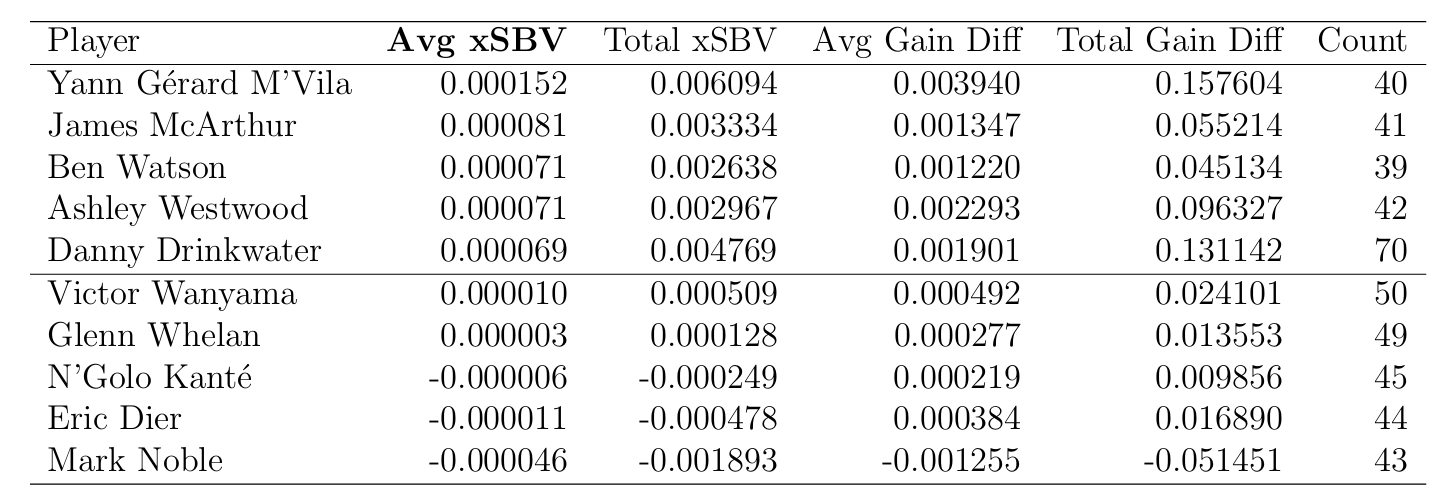
<p>Now for the main result of this thesis, the xSBV for players. The table below shows the average
xSBV for players with more than thirty-eight second ball wins. The cumulative xSBV is
also shown along with the average and cumulative gain difference. The total number of
second balls won from each player is also listed. It is noted that second ball wins that
are won and transitioned into the same zone are not counted since the gain would equal
zero. The zones that are not counted are a significant limitation of the xSBV model and
are discussed in the limitations section towards the end.</p>

<p><img src="https://jack-sears.github.io/blog/assets/images/xsbv_player.png" alt="player-xsbv" /></p>

<p>Yann Gerard M’Vila leads the list with the highest average xSBV (0.000152), supported by a relatively strong total gain differential (0.1576) across 40 events. The others in the top 5 have similar average xSBV scores, but considerably lower then M’vila. Therefore, in terms of creating value from second ball wins, it is concluded that Yann M’vila is the best. As a midfielder from Sunderland who would not widely be regarded as a “top” midfielder, it is exciting that the metric shows him as the best in the Premier League with respect to improving a team’s chances of scoring from second ball wins. Looking back at the Premier League table, we notice that Sunderland finished in 17th place, avoiding relegation by one spot.</p>

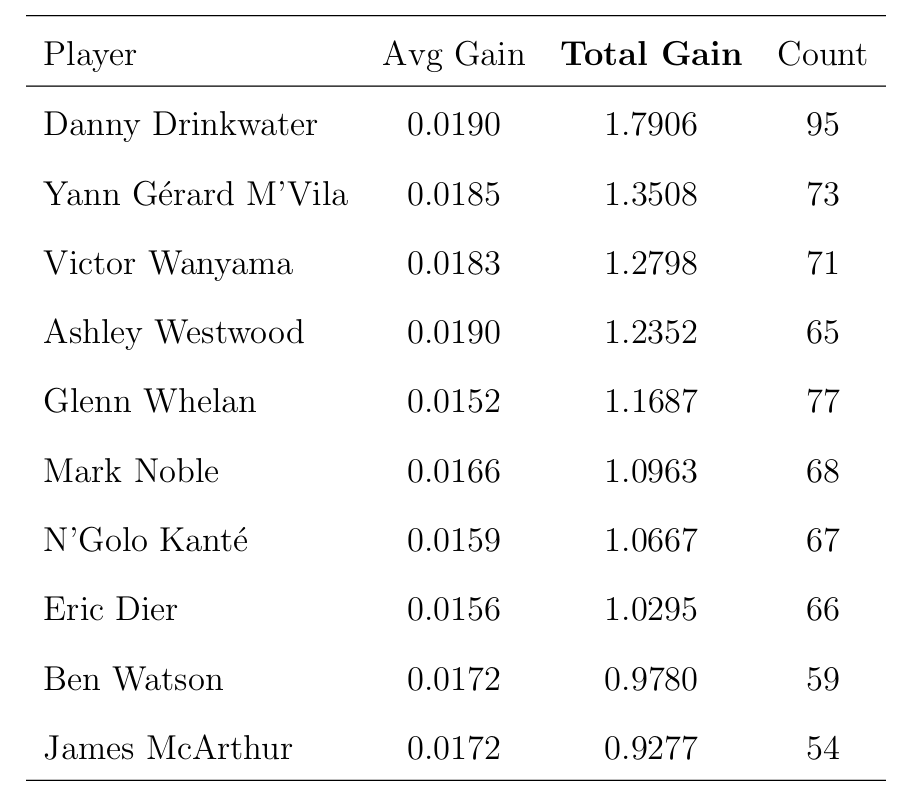
<p>At the opposite end, Victor Wanyama and Glenn Whelan post near-zero averages, and N’Golo Kante, Eric Dier, and Mark Noble register negative values. However, it is crucial to note that these metrics only capture the probability of goals and do not reflect defensive value. Many of the lower-ranked players are defensive midfielders whose primary role is to disrupt opposition play and secure possession with safe passes. Without the value of the opponent winning the ball, we cannot fully capture the importance of these players. However, we can use average gain and cumulative gain and cumulative gain to get a better idea of their importance.</p>

<p><img src="https://jack-sears.github.io/blog/assets/images/gain_player.png" alt="gain-player" /></p>

<p>Even without accounting for defensive contribution, the table above shows the importance
of defensive midfielders. Victor Wanyama and Glenn Whelan both have entered the top
5 comparatively, while the rest have similar scores. So by using part of the full metric,
the zonal value of player’s second ball wins can be seen.</p>

<h2 id="team-analysis">Team Analysis</h2>

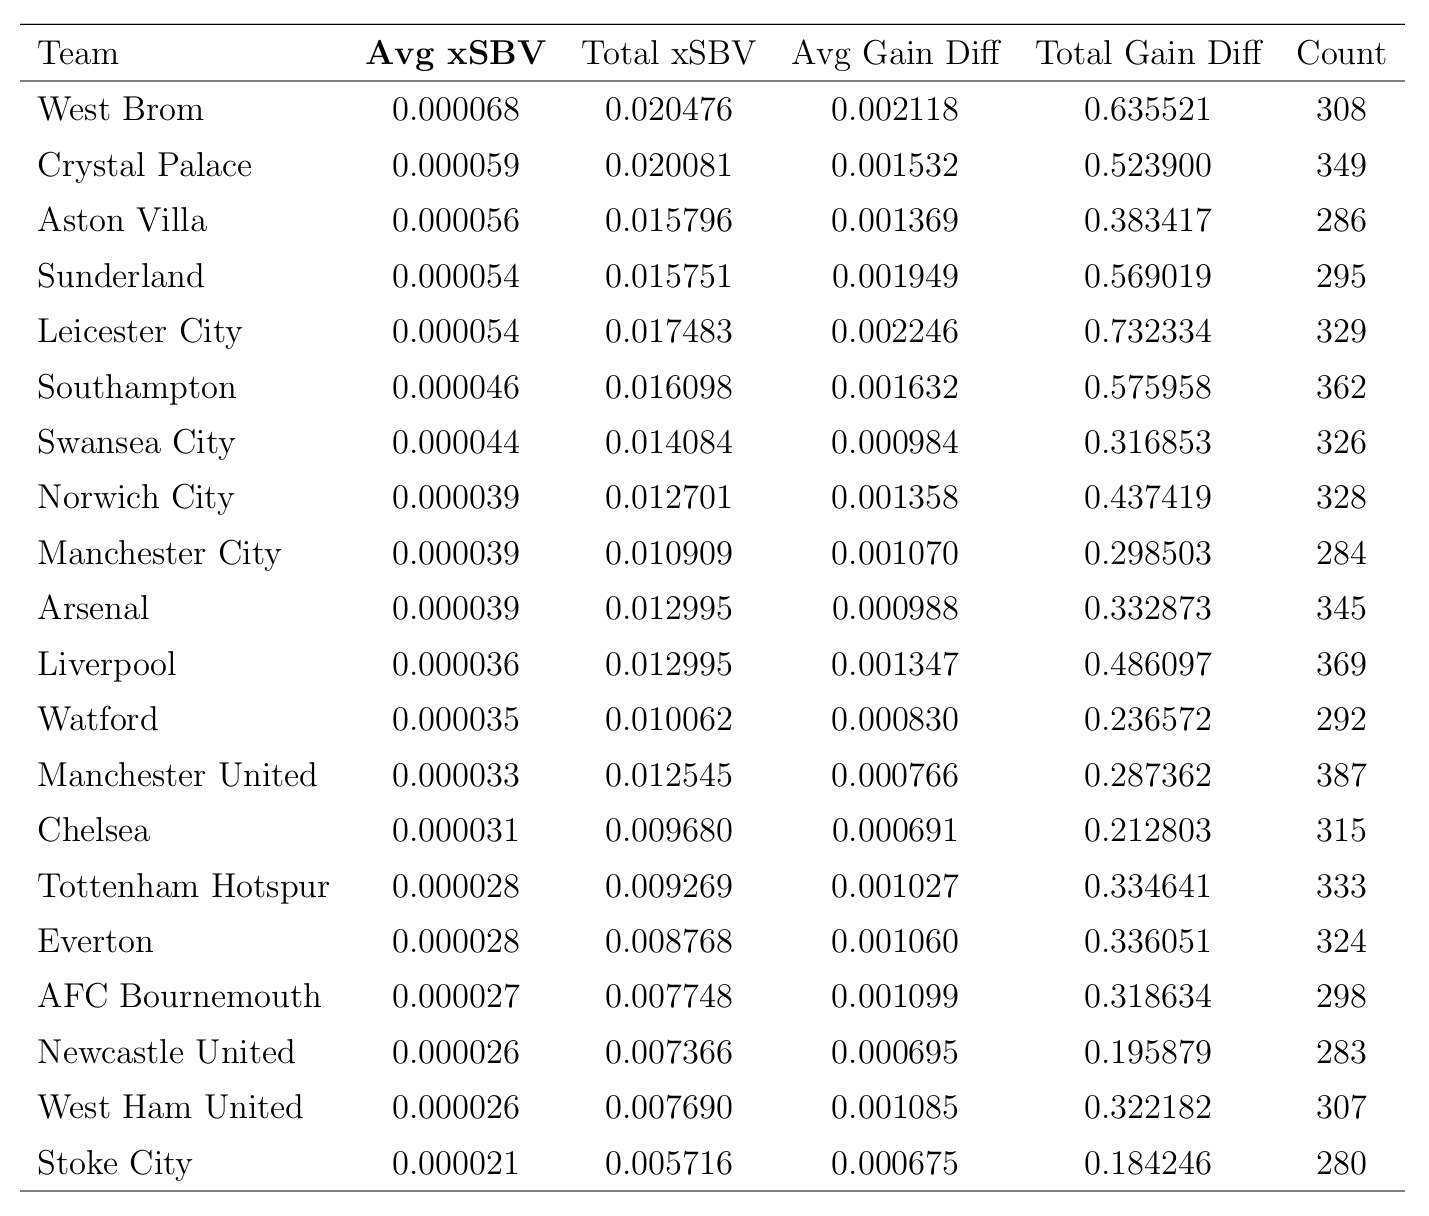
<p>Now, the xSBV scores per team can be analyzed. Again, the teams are ranked in order of highest xSBV to lowest.</p>

<p><img src="https://jack-sears.github.io/blog/assets/images/xsbv_team.png" alt="team-xsbv" /></p>

<p>The above figure reveals some interesting results. Originally, it was thought that lower table
teams would have worse xSBV, but that is not necessarily the case. A more reasonable
explanation would be that high xSBV would be associated with teams with a direct,
long-ball play style. So it makes sense that worse teams already focus on quick attacks
following second ball wins. However, not all lower table teams have high xSBV. For
example, Newcastle, the team that was closest to avoiding relegation, had the third
worst xSBV score. The lower score indicates that Newcastle could have benefited from
improvements in attacking play following second ball wins. Cases like Newcastle are
exactly who this metric is geared toward. There is a possibility that if Newcastle had
worked to improve their xSBV, they could have avoided relegation.</p>

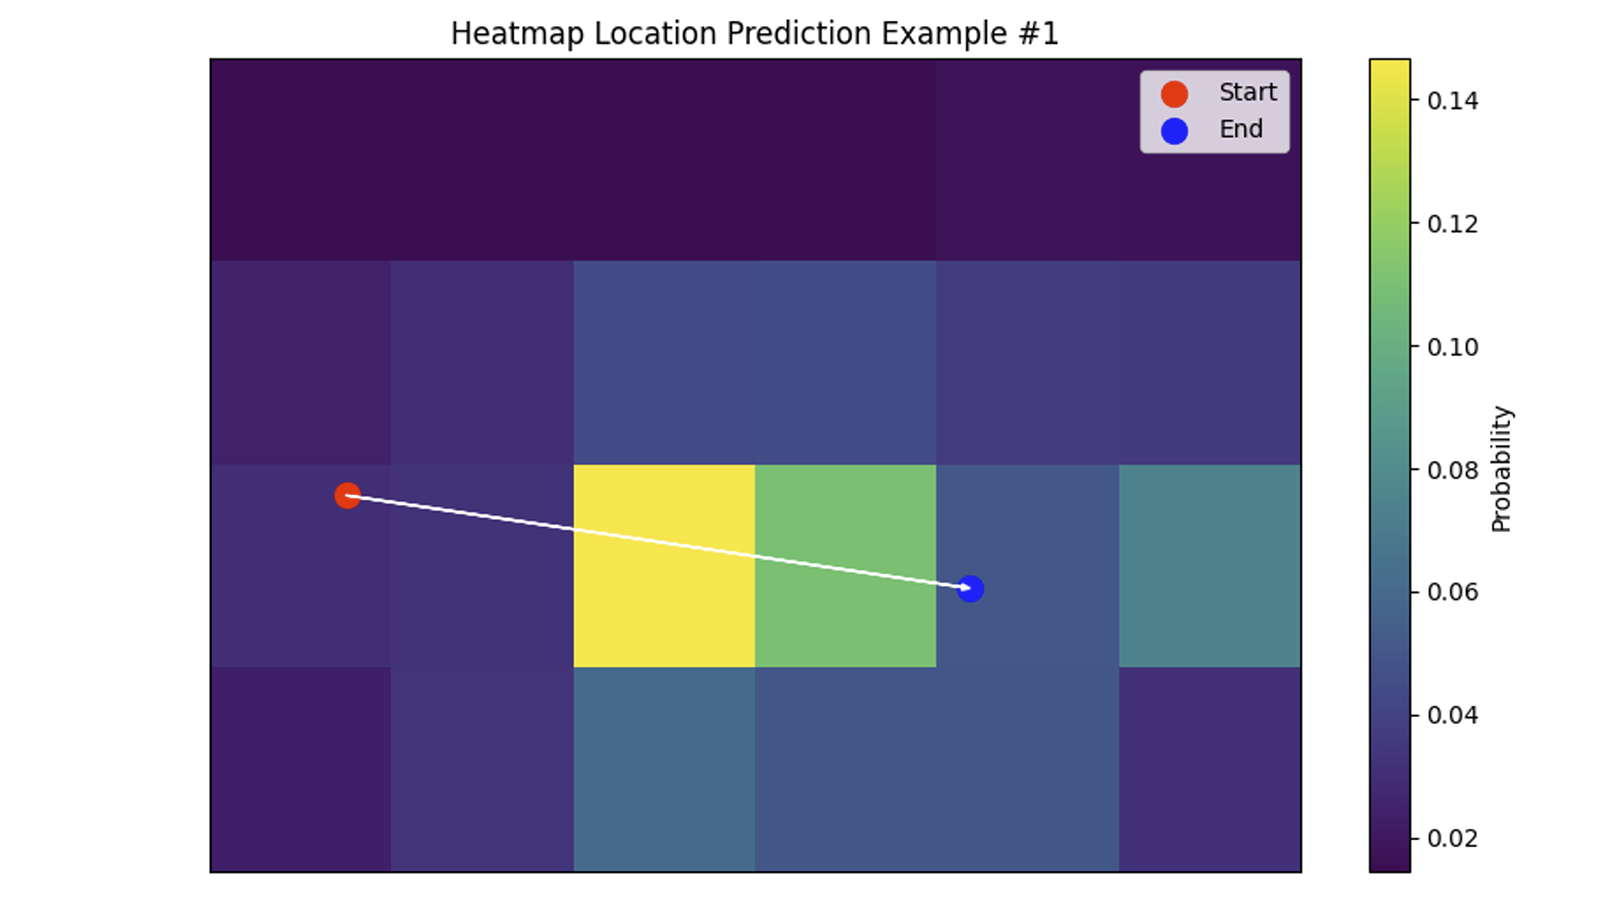
<p>To provide coaches and players with tactical guidance for winning second balls, heat maps
are presented, which show trends of where second balls are likely to land. Although the
location prediction component does not predict zones with high accuracy, it does seem
to understand the spatial relationships of second ball win locations. As component
performance is improved, a similar location distribution is expected, but with higher
prediction accuracy.</p>

<p><img src="https://jack-sears.github.io/blog/assets/images/tactics.png" alt="team-tactic" /></p>

<p>However, from the above figure, it can be shown that a long ball from
zone 12 to 16 is most likely to fall into zones 13 and 14. It is also noted that zone 17
has the next highest probability. Therefore, a tactic could be to target zone 16 from goal
kicks with many players in zones 13 and 14, with a few players running in behind to
zone 17 for flick-on headers. This is one example, but by looking at team-specific visuals
of where past success occurred, coaches can use the ideas from the location prediction
component to create new tactics for their team.</p>

<h2 id="limitations-and-future-work">Limitations and Future Work</h2>

<p>It goes without saying as my first real attempt at football analytics and modelling, this novel work has no shortcoming of limitations. With many of these limitations however, come new questions and future work that can be built upon.</p>

<p>The biggest limitation belongs to the data used. Without access to tracking data, event data was used, almost certaintly missing out on valuable predictive information that would help strengthen the model. Knowing the locations of players should help improve predictions on all fronts, from where the second ball occurs to which team is most likely to win it. A natural extension would be to reproduce these components with tracking data to see how accuracy improves.</p>

<p>Also, the methodology is inherently flawed as manual annotation of games were used to identify second ball scenarios. Certain edge cases are very likely to have been missed, meaning there still is no way to extract all second balls with 100% accuracy. That being said this method still provides a way to highly increase the speed at which many second balls can be extracted, compared to manually having to annotate games by hand.</p>

<p>Set pieces are also not included in the analysis. This was due to scope of research and the difference in nature of open play and set pieces. I believe results most likely would be different and so including set pieces in the same analysis could have taken away from the results. A simple extension to investigate second balls from set pieces would be a natural and interesting pathway forward.</p>

<p>Also, only second ball wins were analyzed. In reality, ignoring second balls where possession was not established contributes to a lower number of second balls per game, and potential game dynamics that are left unexplored. For example, second balls where possession is never immediately established maybe is where real oppurtunity lies for teams to improve on their number of second ball wins.</p>

<p>For the gain component, the model assigns scores by using the difference in probability of scoring a goal within the near future from two different zones. The problem is that if the second ball winner gets the ball and transitions it to the same zone, the resulting difference in gain would equal zero. In reality, the difference should not be zero since winning the second ball itself provides value for your team, regardless of where you transition it to. Continuing with this, the defensive value of winning a second ball is massive as it is stopping your opponent from making transitions that improve their teams chances of scoring, which is not inlcluded in gain since its purely a goal scoring metric. Improving or creating a new way to understand the value second ball wins add to the defense as well as the attack is a natural extension.</p>

<p>Last, the values from the xSBV model are hard to interpret. Since the values from each component are very small due to accuracy of components, the xSBV becomes very small. In retrospect, the need to combine all components into a single output was probably not necessary as each part by itself can be useful in its own right. The idea of having a single metric with a fancy name definetly sucked me in. However, the metric can still be used as comparing players within the metric still works as the scores are relative. Thus, we still established rankings of players and teams.</p>

<p>This is by no means as an exhaustive list, and there’s many more in my actual thesis. I wanted to get my favorite limitations and ideas for future work in this post as I think they may have the most value in providing others with ideas while understanding where my work falls short.</p>

<h2 id="conclusions">Conclusions</h2>

<p>If you have made it this far, I would like to say thanks! This thesis marked a big chapter in my life and I am glad that I was able to shrink it down into a (somewhat) more tolerable verision. At the beginning I had two simple goals. The first to follow my passions and create a project in football analytics. The second was to come up with an idea that was relatively (if at all) unresearched and see what I could come up with. Although, it is nothing ground breaking, I am quite proud to have seen it through from start to finish. Along with that I think there are some cool ideas and insights sprinkled throughout and I have definitely learned a lot and will be a better researcher and football analyst beacuse of it. I look forward to continuing improving my analytics skills and hopefully create cooler and better things in the future. As always any comments or feedback would be appreciated so feel free to reach out on Twitter or email.</p>

<p>Jack Sears</p>]]></content><author><name></name></author><category term="notes" /><summary type="html"><![CDATA[In part 1, we looked into building upon Hang’s framework for extracting second ball wins from data and incorporated our own ideas such as high-order balls to create player and team statistics and heatmaps. Feel free to give it a read but if you haven’t, all you need to know for this post is the two following points.]]></summary></entry><entry><title type="html">The Quantification and Analysis of Second Balls in Football Part 1</title><link href="https://jack-sears.github.io/blog/notes/2026/06/19/quantifyingSB.html" rel="alternate" type="text/html" title="The Quantification and Analysis of Second Balls in Football Part 1" /><published>2026-06-19T00:00:00+00:00</published><updated>2026-06-19T00:00:00+00:00</updated><id>https://jack-sears.github.io/blog/notes/2026/06/19/quantifyingSB</id><content type="html" xml:base="https://jack-sears.github.io/blog/notes/2026/06/19/quantifyingSB.html"><![CDATA[<p>The evaluation of in-game actions of football players and how they affect the outcome
of a game is an important part of football analytics <a href="https://link.springer.com/book/10.1007/978-3-658-21177-6">(Link, 2018)</a>. Unlike traditional
statistics that focus on goals and assists, evaluating other actions that players perform
looks deeper into the nuances of player behaviour and decision-making.</p>

<p>An action that often goes unnoticed is the ability to win second balls <a href="https://lchunhang.medium.com/quantifying-second-ball-wins-d626ac56f108">(Hang, 2023)</a>. A second
ball is a possession gain following an intervention from an attempted long pass. Simply
put, a second ball occurs after the ball is kicked long and neither team clearly controls
it. Instead, the ball bounces, gets deflected, or is contested, and then players rush
to try and take control of the ball. A quote from Pep Guardiola,
one of the most successful football managers of all time, states the importance of winning second
balls, ”The main thing in English football is to control the second ball. Without that,
you cannot survive.” <a href="https://www.theguardian.com/football/blog/2016/dec/14/pep-guardiola-ronald-koeman-manchester-city-everton-full-english">(Wilson, 2016)</a>.</p>

<p>Despite the importance of winning second balls, there is a lack of research quantifying
or analyzing the value of winning second balls and how to do so successfully. Therefore this part 1 of 2 post aims to extend the research done and pose future direction for further work/extensions.</p>

<h2 id="definition-and-example">Definition and Example</h2>

<p>Let’s begin by establishing a working definition for second balls. The following definitions have been adapted from a <a href="https://lchunhang.medium.com/quantifying-second-ball-wins-d626ac56f108">blog</a> post by Chun Hang, but remain largely unchanged since I think they are a great definition.</p>

<div class="definition">
  <div class="box-title">Definition 1 — Second Ball</div>
  The loose ball that results from an intervention following a long pass or clearance.
  <ol>
    <li>Long Pass (long ball): A pass with a length of 20 metres or greater that any player meets, successful or not. </li>
    <li>Interventions: The first point of contact with the long ball must be an intervention. This intervention can be in the form of an aerial duel between players, a clearance attempt, or miscontrol. The key part of the interaction is that it leads to a loose ball.</li>
    
  </ol>
  
</div>

<div class="definition">
  <div class="box-title">Definition 2 - Second Ball Win</div>
  A possession gain or regain immediately following a second ball.
  <ol>
   <li>Possession Gain/Regain: A player controls the second ball gaining or regaining possession for their team. Including the player with the ball, their team must complete two successful actions to be considered a second ball win.</li>
  </ol>
</div>

<p>And to further build intuition for those who are less familiar with second balls, I think seeing a real example does a great job.</p>

<video width="720" controls="" playsinline="" preload="auto">
  <source src="https://jack-sears.github.io/blog/assets/ADBA_example.mp4" type="video/mp4" />
</video>

<p>It is clear from the example that second balls can lead to chaotic and quick transitional moments. Before beginning to quantify them, let’s investigate their importance a little bit more.</p>

<h2 id="importance-of-second-balls">Importance of Second Balls</h2>

<p>The following brief analysis examines the relationship between second ball success, goal difference, and overall team performance. It should not be taken as fact but rather a thought provoking analysis to give reason why we should investigate second balls further.</p>

<h3 id="league-performance">League Performance</h3>

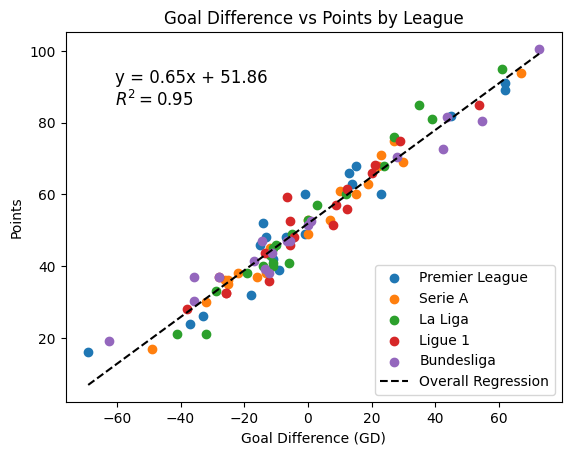
<p>Using data from the top 5 European leagues in 2015/2016, a linear regression is performed on goal difference (GD) vs total points earned in a season.</p>

<p><img src="/blog/assets/images/gd_vs_pts.png" alt="Alt text" /></p>

<p>An R² value of 0.95 demonstrates a strong linear relationship between GD and points. Based on the regression an increase in GD by 1 corresponds to an expected points increase of 0.65 points. Potentially even marginal improvements in GD can affect a team’s league standing position.</p>

<h3 id="shot-creation">Shot Creation</h3>

<p>Now, let’s look at the role second balls play in generating goal-scoring opportunities. The following information is extracted from the dataset:</p>
<ul>
  <li>19.38% of second ball wins result in a shot within the following possession.</li>
  <li>The average expected goal (xG) value per shot is 10.1%.</li>
  <li>On average teams contest approximately 24 second balls per game.</li>
</ul>

<p>The above list suggest increasing second ball wins could lead to a higher number of shots for a team. Also note, expected goals is a metric that predicts the probability that a shot results in a goal by using various features such as distance to goal, angle to goal, etc.</p>

<h3 id="impact-of-winning-more-second-balls">Impact of Winning More Second Balls</h3>

<p>Now let’s look at the potential impact on a team that wins an additional 5 second balls per match. Based on the dataset:</p>

<ul>
  <li>Approximately 0.97 additional shots per game, or 36.81 additional shots per season (for a standard 38 game season).</li>
  <li>Given an average xG per shot of 0.101, this translates to 3.72 expected goals gined per season.</li>
  <li>Conversely, by preventing the opponent from winning these second balls, a team can reduce shots conceded, preventing 3.72 expected goals against per season.</li>
  <li>Thus, a team could see a net gain as large as 7.44 GD per season.</li>
</ul>

<h3 id="translating-second-ball-success-to-league-points">Translating Second Ball Success to League Points</h3>

<p>Finally, by using the regression model, a 7.44 GD corresponds to an additional 4.84 points over a season. It may not seem like much, but minor differences in points can define team’s seasons as success or failure. Below is the league table from the 2015/2016 premier league, where the data is taken from.</p>

<table>
  <thead>
    <tr>
      <th>Rank</th>
      <th>Team</th>
      <th>Points</th>
    </tr>
  </thead>
  <tbody>
    <tr style="background-color: rgba(46, 204, 113, 0.5);">
      <td>1</td><td>Leicester City</td><td>81</td>
    </tr>
    <tr style="background-color: rgba(241, 196, 15, 0.5);">
      <td>2</td><td>Arsenal</td><td>71</td>
    </tr>
    <tr style="background-color: rgba(241, 196, 15, 0.5);">
      <td>3</td><td>Tottenham</td><td>70</td>
    </tr>
    <tr style="background-color: rgba(241, 196, 15, 0.5);">
      <td>4</td><td>Manchester City</td><td>66</td>
    </tr>
    <tr style="background-color: rgba(241, 196, 15, 0.5);">
      <td>5</td><td>Manchester United</td><td>66</td>
    </tr>
    <tr><td>6</td><td>Southampton</td><td>63</td></tr>
    <tr><td>7</td><td>West Ham</td><td>62</td></tr>
    <tr><td>8</td><td>Liverpool</td><td>60</td></tr>
    <tr><td>9</td><td>Stoke City</td><td>51</td></tr>
    <tr><td>10</td><td>Chelsea</td><td>50</td></tr>
    <tr><td>11</td><td>Everton</td><td>47</td></tr>
    <tr><td>12</td><td>Swansea City</td><td>47</td></tr>
    <tr><td>13</td><td>Watford</td><td>45</td></tr>
    <tr><td>14</td><td>West Brom</td><td>43</td></tr>
    <tr><td>15</td><td>Crystal Palace</td><td>42</td></tr>
    <tr><td>16</td><td>Bournemouth</td><td>42</td></tr>
    <tr><td>17</td><td>Sunderland</td><td>39</td></tr>
    <tr style="background-color: rgba(231, 76, 60, 0.5);">
      <td>18</td><td>Newcastle</td><td>37</td>
    </tr>
    <tr style="background-color: rgba(231, 76, 60, 0.5);">
      <td>19</td><td>Norwich City</td><td>34</td>
    </tr>
    <tr style="background-color: rgba(231, 76, 60, 0.5);">
      <td>20</td><td>Aston Villa</td><td>17</td>
    </tr>
  </tbody>
</table>

<div style="display: flex; gap: 20px; margin-top: 10px; margin-bottom: 30px;">
  <div style="display: flex; align-items: center; gap: 6px;">
    <div style="width: 16px; height: 16px; background-color: rgba(46, 204, 113, 0.5); border: 1px solid rgba(46, 204, 113, 0.8);"></div>
    <span>Champions</span>
  </div>
  <div style="display: flex; align-items: center; gap: 6px;">
    <div style="width: 16px; height: 16px; background-color: rgba(241, 196, 15, 0.5); border: 1px solid rgba(241, 196, 15, 0.8);"></div>
    <span>European Qualification</span>
  </div>
  <div style="display: flex; align-items: center; gap: 6px;">
    <div style="width: 16px; height: 16px; background-color: rgba(231, 76, 60, 0.5); border: 1px solid rgba(231, 76, 60, 0.8);"></div>
    <span>Relegation</span>
  </div>
</div>

<p>It is clear to see minor point differences between Newcastle (37) and Sunderland (39). Two points was the difference between relegation and staying in the Premier League. Also, 4 points seperate 4th-7th, the difference between two European spots. Given the stakes, I argue that for certain teams, improving second ball success could potenitally be season changing.</p>

<h2 id="other-second-ball-research">Other Second Ball Research</h2>

<p>To date, only one research <a href="https://www.tandfonline.com/doi/full/10.1080/24748668.2025.2462399">paper</a> has directly analyzed second balls, while few online blogs/articles offer exploratory analyses (<a href="https://lchunhang.medium.com/quantifying-second-ball-wins-d626ac56f108">(Hang, 2023)</a> and <a href="https://www.nytimes.com/athletic/6193329/2025/03/13/measuring-second-balls-premier-league-analysis/">(Carey &amp; Walid, 2025)</a>).</p>

<p><a href="https://www.tandfonline.com/doi/full/10.1080/24748668.2025.2462399">Sunjic et al.</a> analyze how second ball wins correlate with technical performance such as shots, passes, and dribbles. <a href="https://www.nytimes.com/athletic/6193329/2025/03/13/measuring-second-balls-premier-league-analysis/">Carey and Walid</a> provide really cool graphics about premier league teams abilities from winning second balls to even looking at the number of defensive vs offensive second balls won for each team. While both very interesting, neither provide a clear mathematical definition that allows for algorithmic extraction.</p>

<p><a href="https://lchunhang.medium.com/quantifying-second-ball-wins-d626ac56f108">Hang</a> addresses this problem by creating an idea called “Second Ball Chains”, a chain of events that denote the actions leading up to a second ball. An example can be found below.</p>

<svg viewBox="0 0 1050 120" xmlns="http://www.w3.org/2000/svg" style="width:100%;max-width:1050px">
  <defs>
    <marker id="arrow" markerWidth="10" markerHeight="7" refX="10" refY="3.5" orient="auto">
      <polygon points="0 0, 10 3.5, 0 7" fill="#94a3b8" />
    </marker>
  </defs>

  <!-- Box 1 -->
  <rect x="10" y="20" width="170" height="60" rx="5" fill="#e2e8f0" stroke="#94a3b8" />
  <text x="95" y="47" text-anchor="middle" font-size="13" fill="#1e293b">Team A</text>
  <text x="95" y="63" text-anchor="middle" font-size="13" fill="#1e293b">Unsuccesful Long Pass</text>

  <!-- Arrow 1 -->
  <line x1="180" y1="50" x2="210" y2="50" stroke="#94a3b8" stroke-width="2" marker-end="url(#arrow)" />

  <!-- Box 2 -->
  <rect x="210" y="20" width="170" height="60" rx="5" fill="#e2e8f0" stroke="#94a3b8" />
  <text x="295" y="47" text-anchor="middle" font-size="13" fill="#1e293b">Team B</text>
  <text x="295" y="63" text-anchor="middle" font-size="13" fill="#1e293b">Successful Aerial Duel</text>

  <!-- Arrow 2 -->
  <line x1="380" y1="50" x2="410" y2="50" stroke="#94a3b8" stroke-width="2" marker-end="url(#arrow)" />

  <!-- Box 3 -->
  <rect x="410" y="20" width="170" height="60" rx="5" fill="#e2e8f0" stroke="#94a3b8" />
  <text x="495" y="47" text-anchor="middle" font-size="13" fill="#1e293b">Team A</text>
  <text x="495" y="63" text-anchor="middle" font-size="13" fill="#1e293b">Unsucessful Aerial Duel</text>

  <!-- Arrow 3 -->
  <line x1="580" y1="50" x2="610" y2="50" stroke="#94a3b8" stroke-width="2" marker-end="url(#arrow)" />

  <!-- Box 4 -->
  <rect x="610" y="20" width="170" height="60" rx="5" fill="#e2e8f0" stroke="#94a3b8" />
  <text x="695" y="47" text-anchor="middle" font-size="13" fill="#1e293b">Team B</text>
  <text x="695" y="63" text-anchor="middle" font-size="13" fill="#1e293b">Unsuccessful Pass/Clearance</text>

  <!-- Arrow 4 -->
  <line x1="780" y1="50" x2="810" y2="50" stroke="#94a3b8" stroke-width="2" marker-end="url(#arrow)" />

  <!-- Box 5 -->
  <rect x="810" y="20" width="170" height="60" rx="5" fill="#e2e8f0" stroke="#94a3b8" />
  <text x="895" y="47" text-anchor="middle" font-size="13" fill="#1e293b">Team A</text>
  <text x="895" y="63" text-anchor="middle" font-size="13" fill="#1e293b">Successful Action</text>
</svg>
<p>The two problems I am trying to address in this post are:</p>
<ul>
  <li>Naming Conventions</li>
  <li>Higher-order balls (third balls, fourth balls, and so on)</li>
</ul>

<h2 id="second-ball-chains">Second Ball Chains</h2>

<p>The original second ball chains naming convention can be confusing. For example, ABABA means Team A long ball, followed by an aerial duel in which Team B wins, followed by Team A gaining the ball from the duel. I argue this is not clear from the above example. Instead it should look something like this (ADBA):</p>

<svg viewBox="0 0 520 120" xmlns="http://www.w3.org/2000/svg" style="width:100%;max-width:600px">
  <defs>
    <marker id="arrow" markerWidth="10" markerHeight="7" refX="10" refY="3.5" orient="auto">
      <polygon points="0 0, 10 3.5, 0 7" fill="#94a3b8" />
    </marker>
  </defs>

  <!-- Box 1 -->
  <rect x="10" y="20" width="140" height="60" rx="5" fill="#e2e8f0" stroke="#94a3b8" />
  <text x="80" y="47" text-anchor="middle" font-size="14" fill="#1e293b">Team A</text>
  <text x="80" y="63" text-anchor="middle" font-size="14" fill="#1e293b">Long Pass</text>

  <!-- Arrow 1 -->
  <line x1="150" y1="50" x2="190" y2="50" stroke="#94a3b8" stroke-width="2" marker-end="url(#arrow)" />

  <!-- Box 2 -->
  <rect x="190" y="20" width="140" height="60" rx="5" fill="#e2e8f0" stroke="#94a3b8" />
  <text x="260" y="47" text-anchor="middle" font-size="14" fill="#1e293b">Duel</text>
  <text x="260" y="63" text-anchor="middle" font-size="14" fill="#1e293b">Team B Wins</text>

  <!-- Arrow 2 -->
  <line x1="330" y1="50" x2="370" y2="50" stroke="#94a3b8" stroke-width="2" marker-end="url(#arrow)" />

  <!-- Box 3 -->
  <rect x="370" y="20" width="140" height="60" rx="5" fill="#e2e8f0" stroke="#94a3b8" />
  <text x="440" y="47" text-anchor="middle" font-size="14" fill="#1e293b">Team A</text>
  <text x="440" y="63" text-anchor="middle" font-size="14" fill="#1e293b">Gets Ball</text>
</svg>

<p>So instead of only using A’s and B’s, we incorporate ‘D’ for duel to help clarify the chains. Also a ‘w’ is added to the end of a chain to denote a second ball win. For example, ADBA is a second ball, where ADBAw is a second ball win, meaning possession is successfully established. This is another distinction that seperates these chains from Hang’s. A summary of all of our chains will be provided below.</p>

<h3 id="higher-order-balls">Higher Order Balls</h3>

<p>Also, second balls follow a strict set of chains and leave out other scenarios that are very similar. Currently a team is only awarded a second ball win if they complete 2 successful actions. However, what about when neither team intially gains possession and instead the ball hops back and forth between teams a few times before someone establihses possession. These scenarios can be though of as third balls, fourth balls, and so on, depending on how long it stays in this transitional state. Although they are not second balls, I still include them since they serve the same purpose; helping to understand the relationship between chaotic interactions after a long ball and how they affect goal-scoring opportunities. We call this new concept, Higher-Order Balls, and use the following definitions to describe them.</p>

<div class="definition">
  <div class="box-title">Definition 3 - Transition Window</div>
  A fixed time period (e.g., 5 seconds) following when a second ball occurs, during which both teams have the opportunity to establish possession.
</div>

<div class="definition">
  <div class="box-title">Definition 4 - Higher-Order Balls</div>
  A higher order ball refers to a scenario where a team initially gains the second ball but fails to establish immediate possession (i.e., does not complete two consecutive successful actions right away).
</div>

<div class="definition">
  <div class="box-title">Definition 5 - Higher-Order Ball Win</div>
  A Higher-Order Ball Win occurs when a team is able to establish possession during the transition window after a second ball occurs.
</div>

<p>A ‘T’ can be used to denote a transition period. So ADBA which is above, can also now be extended further into two higher-order ball scenarios, ADBATA and ADBATB.</p>

<h3 id="updated-chains">Updated Chains</h3>

<p>With the new naming conventions the following second ball chains can be summarized:</p>

<table>
  <thead>
    <tr>
      <th>Chain</th>
      <th>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>ABA</strong></td>
      <td>Team A long ball, Team B pass/clearance, Team A gets ball</td>
    </tr>
    <tr>
      <td><strong>ABB</strong></td>
      <td>Team A long ball, Team B pass/clearance, Team B gets ball</td>
    </tr>
    <tr>
      <td><strong>ADBA</strong></td>
      <td>Team A long ball, Team B wins duel, Team A gets ball</td>
    </tr>
    <tr>
      <td><strong>ADBB</strong></td>
      <td>Team A long ball, Team B wins duel, Team B gets ball</td>
    </tr>
    <tr>
      <td><strong>ADAA</strong></td>
      <td>Team A long ball, Team A wins duel, Team A gets ball</td>
    </tr>
    <tr>
      <td><strong>ADAB</strong></td>
      <td>Team A long ball, Team A wins duel, Team B gets ball</td>
    </tr>
    <tr>
      <td><strong>ABATA</strong></td>
      <td>ABA, transition period, Team A establishes possession</td>
    </tr>
    <tr>
      <td><strong>ABATB</strong></td>
      <td>ABA, transition period, Team B establishes possession</td>
    </tr>
    <tr>
      <td><strong>ABBTA</strong></td>
      <td>ABB, transition period, Team A establishes possession</td>
    </tr>
    <tr>
      <td><strong>ABBTB</strong></td>
      <td>ABB, transition period, Team B establishes possession</td>
    </tr>
    <tr>
      <td><strong>ADBATA</strong></td>
      <td>ADBA, transition period, Team A establishes possession</td>
    </tr>
    <tr>
      <td><strong>ADBATB</strong></td>
      <td>ADBA, transition period, Team B establishes possession</td>
    </tr>
    <tr>
      <td><strong>ADBBTA</strong></td>
      <td>ADBB, transition period, Team A establishes possession</td>
    </tr>
    <tr>
      <td><strong>ADBBTB</strong></td>
      <td>ADBB, transition period, Team B establishes possession</td>
    </tr>
    <tr>
      <td><strong>ADAATA</strong></td>
      <td>ADAA, transition period, Team A establishes possession</td>
    </tr>
    <tr>
      <td><strong>ADAATB</strong></td>
      <td>ADAA, transition period, Team B establishes possession</td>
    </tr>
    <tr>
      <td><strong>ADABTA</strong></td>
      <td>ADAB, transition period, Team A establishes possession</td>
    </tr>
    <tr>
      <td><strong>ADABTB</strong></td>
      <td>ADAB, transition period, Team B establishes possession</td>
    </tr>
  </tbody>
</table>

<p>Note that for the first 6 chains, a ‘w’ can be added to the end to denote a second ball win. For the latter 12, since a transition period ends with establishing possession, they inherently are wins and do not require a ‘w’.</p>

<h2 id="second-ball-possessions">Second Ball Possessions</h2>

<p>Now that we have updated second ball chains, we now define what happens after a second ball win: a second ball possession. The following defintion sets up future analysis (my <a href="https://jack-sears.github.io">next</a> post).</p>

<div class="definition">
  <div class="box-title">Definition 6 - Second Ball Possession</div>
  The sequence of events after a second ball win until there is a stoppage in play or the opposing team establishes possession.
</div>

<h2 id="mathematical-definition-of-second-ball-wins">Mathematical Definition of Second Ball Wins</h2>

<p>Now we define them mathematically to allow for automated extraction from a dataset.</p>

<p>Let’s define a second ball sequence $S$ that begins at time $t_0$ when a second ball occurs. Let $T$ be a team and $W_s$ be a second ball win.</p>

\[W_s = \begin{cases} 1, &amp; \text{if } T \text{ completes 2 consecutive passes within } t_0 + \tau \\ 0, &amp; \text{otherwise} \end{cases}\]

<p>where $\tau$ is the transition window. The transition period is defined as:</p>

\[T_{trans} = [t_o, t_f]\]

<p>where $t_f = min(t_{S_{A}=2}, t_{S_{B}=2}, t_0 + \tau)$ and $t_{S_{x}=y}$ is the time $t$, at which team $x$ makes $y$ successful actions.</p>

<p>Once $t_f$ is reached, the possession of the winning team is tracked, let’s say $P_T$, until one of the following:</p>

<ul>
  <li>Possession loss, that is, the opposing team completes two consecutive successful actions, a foul, an out of bounds, or any other stoppage.</li>
  <li>Goal</li>
</ul>

<p>Formally:</p>

\[P_T = \{a_{T_1}, a_{T_2}, \ldots, a_{T_n}\}\]

<p>where $a_{T_i}$ is the $i$th successful action by team $T$. Therefore, $a_{T_n}$ is a possession loss or a goal.</p>

<h2 id="extraction">Extraction</h2>

<p>With definitions created, 10 games were manually anontated and second balls were sorted into the correct chain categories. Then using python, automated second ball chain extracting functions were created and can be found in the following repo: <a href="https://github.com/jack-sears/second-balls">Second Ball Extracting Functions</a>.</p>

<h2 id="results">Results</h2>

<p>Finally, we have a few results. Similiarly to <a href="https://lchunhang.medium.com/quantifying-second-ball-wins-d626ac56f108">Hang</a>, we can create a rankings for players and teams of second ball wins. Furthermore, we can create visuals that show the locations of every second ball win on a player and team level.</p>

<h3 id="second-ball-rankings">Second Ball Rankings</h3>

<table>
  <thead>
    <tr>
      <th>Player</th>
      <th>Team</th>
      <th>Amount</th>
      <th>p90</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Danny Drinkwater</td>
      <td>Leicester City</td>
      <td>95</td>
      <td>2.82</td>
    </tr>
    <tr>
      <td>Andrew Surman</td>
      <td>AFC Bournemouth</td>
      <td>84</td>
      <td>2.21</td>
    </tr>
    <tr>
      <td>Glenn Whelan</td>
      <td>Stoke City</td>
      <td>77</td>
      <td>2.19</td>
    </tr>
    <tr>
      <td>Yann M’Vila</td>
      <td>Sunderland</td>
      <td>73</td>
      <td>2.06</td>
    </tr>
    <tr>
      <td>Idrissa Gana Gueye</td>
      <td>Everton</td>
      <td>71</td>
      <td>2.08</td>
    </tr>
    <tr>
      <td>Victor Wanyama</td>
      <td>Southampton</td>
      <td>71</td>
      <td>2.55</td>
    </tr>
    <tr>
      <td>Darren Fletcher</td>
      <td>West Brom</td>
      <td>70</td>
      <td>1.87</td>
    </tr>
    <tr>
      <td>Gareth Barry</td>
      <td>Everton</td>
      <td>68</td>
      <td>2.16</td>
    </tr>
    <tr>
      <td>Mark Noble</td>
      <td>West Ham</td>
      <td>68</td>
      <td>1.92</td>
    </tr>
    <tr>
      <td>Claudio Yacob</td>
      <td>West Brom</td>
      <td>67</td>
      <td>2.15</td>
    </tr>
    <tr>
      <td>N’Golo Kante</td>
      <td>Leicester City</td>
      <td>67</td>
      <td>1.99</td>
    </tr>
    <tr>
      <td>Eric Dier</td>
      <td>Tottenham</td>
      <td>66</td>
      <td>1.82</td>
    </tr>
    <tr>
      <td>Cesc Fabregas</td>
      <td>Chelsea</td>
      <td>65</td>
      <td>2.02</td>
    </tr>
    <tr>
      <td>Ashley Westwood</td>
      <td>Aston Villa</td>
      <td>65</td>
      <td>2.15</td>
    </tr>
    <tr>
      <td>Yohan Cabaye</td>
      <td>Crystal Palace</td>
      <td>62</td>
      <td>2.07</td>
    </tr>
  </tbody>
</table>

<p>Again this result is not new, first being shown by <a href="https://lchunhang.medium.com/quantifying-second-ball-wins-d626ac56f108">Hang</a>, it has just been updated to incorporate our new framework including the updated second ball chains and higher order balls.</p>

<h3 id="second-ball-heatmaps">Second Ball Heatmaps</h3>

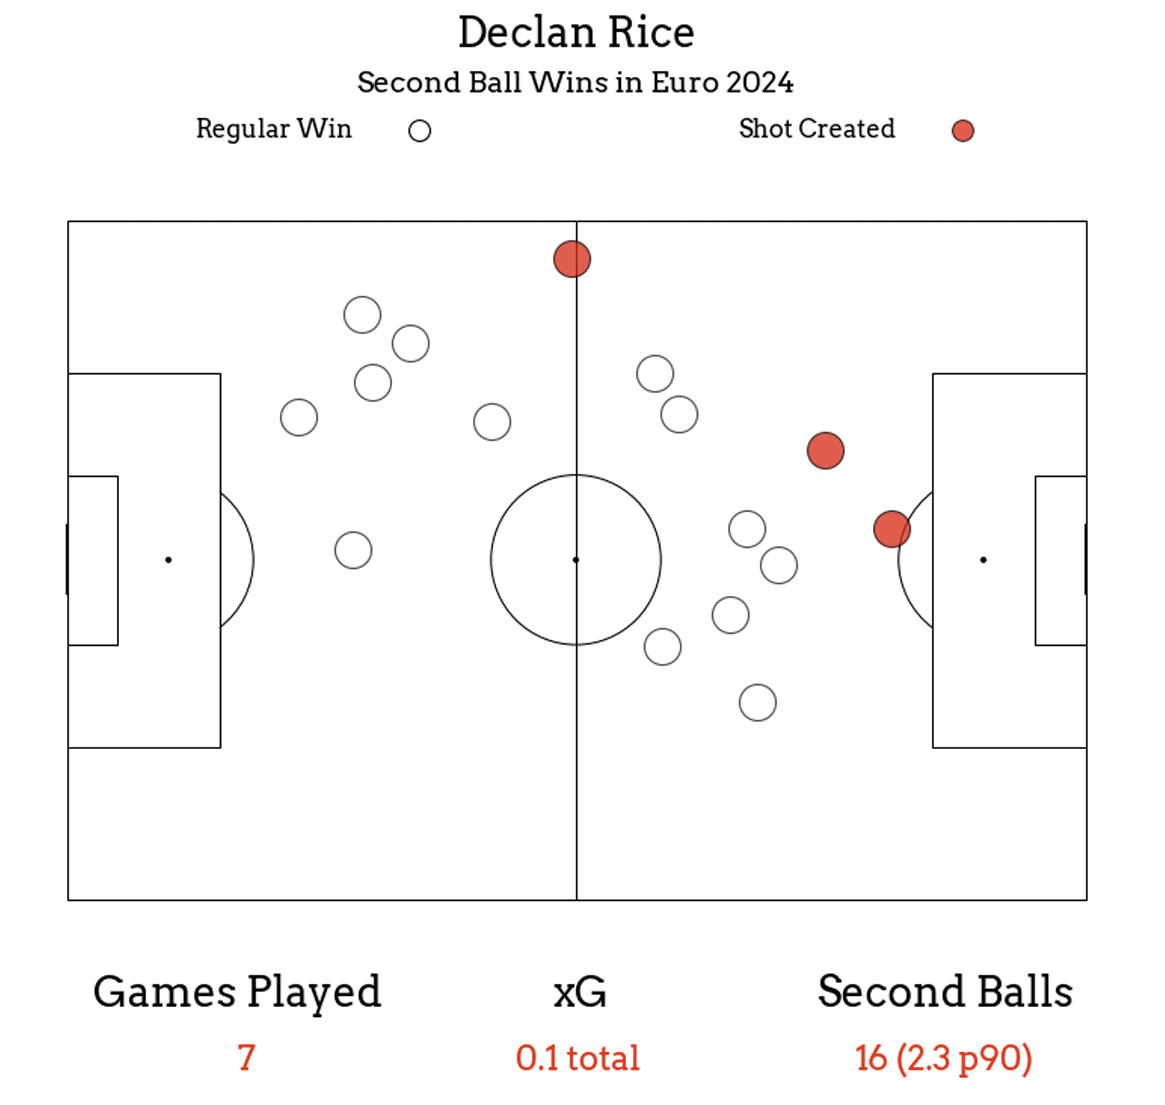
<p>By using the second ball algorithms we can create visuals that show where on the field second balls occur and which result in shots created in the subsequent second ball possession.</p>

<p><img src="https://jack-sears.github.io/blog/assets/images/declan_fig.png" alt="Declan Figure" /></p>

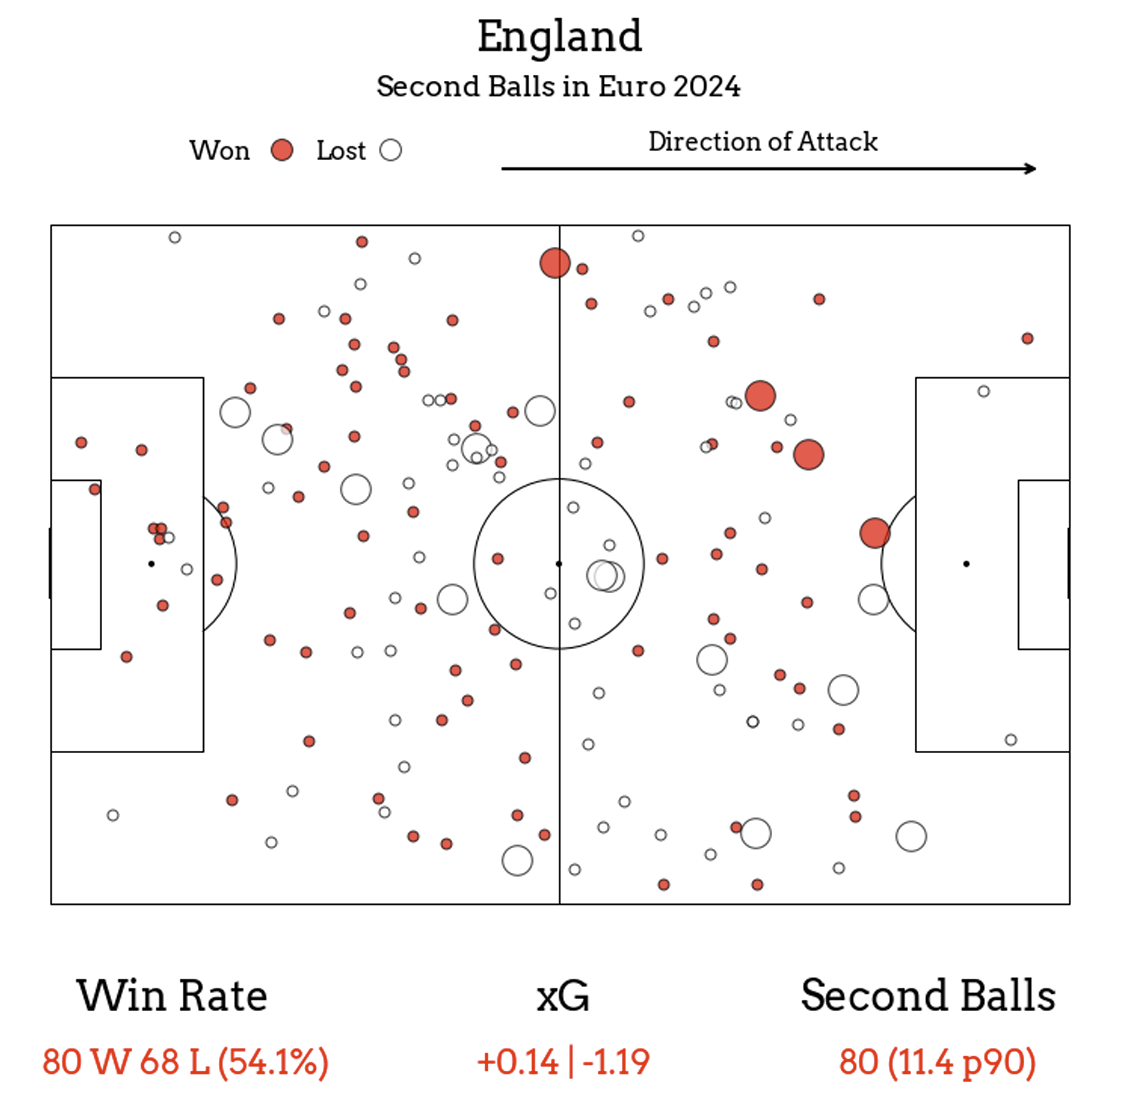
<p>It can also be done for a team, including when they lose a second ball. We can use these maps to visualize players second ball winning habits and which spaces on the pitch they occupy often.</p>

<p><img src="/blog/assets/images/england_fig.png" alt="England Figure" /></p>

<p>Although England won more second balls than they lost, there were more shots conceded than created. A likely explanation is that since England often dominates possession, opposition may focus on counterattacks through a direct, second ball inducing style of play, with the intention of creating attacking chances quickly after possession regain.</p>

<h2 id="limitations">Limitations</h2>

<p>Three main limitations in this post should be addressed. The first is the manual annotation of second balls. Event data is not tagged with second balls so only common second ball scenarios that were observed when watching games were recorded. It is very likely we are missing second ball instances. Still, averaging around 24 second balls per game was enough to conduct analysis and create meaningful work, that should only be able to be solidified with updated, improved extraction.</p>

<p>Second, set pieces were not included. Given the differnce in open play and set pieces, they probably would give different results in analysis and due to scope of this work, were not included. Incorporating set pieces would be a natural extension to this work.</p>

<p>Last, only second ball wins were included. So for the visuals and player rankings, it does not include those second balls where possession was not established. This leaves out an important aspect as player second ball winning efficiency could play an important role, i.e, a player winning 5 second balls in 10 attempts vs a player winning 5 in 7 attempts.</p>

<p>While these limitations leave avenues for future work, this work serves as ground work and an intro into the topic.</p>

<h2 id="conclusions">Conclusions</h2>

<p>In this post we investigated quantifying second balls in football. <a href="https://lchunhang.medium.com/quantifying-second-ball-wins-d626ac56f108">Hang’s</a> framework was built upon, clearing up naming convention confusion as well as introducing higher order balls. Then a mathematical framework was created to allow for conistent extraction of second ball scenarios. Finally player and team statisitics and heatmaps were shown to visualize the quantification of second balls. What has yet to be answered is how second ball wins influence the resulting second ball possesion. Stay tuned for the next post to find out more! Thanks for reading and please feel free to share or leave comments or feedback on Twitter. I am always looking for ways to improve my writing and research skills. Cheers.</p>]]></content><author><name></name></author><category term="notes" /><summary type="html"><![CDATA[The evaluation of in-game actions of football players and how they affect the outcome of a game is an important part of football analytics (Link, 2018). Unlike traditional statistics that focus on goals and assists, evaluating other actions that players perform looks deeper into the nuances of player behaviour and decision-making.]]></summary></entry><entry><title type="html">Predicting the World Cup</title><link href="https://jack-sears.github.io/blog/notes/2026/06/12/worldcupmatchpredictions.html" rel="alternate" type="text/html" title="Predicting the World Cup" /><published>2026-06-12T00:00:00+00:00</published><updated>2026-06-12T00:00:00+00:00</updated><id>https://jack-sears.github.io/blog/notes/2026/06/12/worldcupmatchpredictions</id><content type="html" xml:base="https://jack-sears.github.io/blog/notes/2026/06/12/worldcupmatchpredictions.html"><![CDATA[<script type="text/javascript" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-mml-chtml.js">
</script>

<p>In honour of the start of the 2026 Fifa World Cup and my competitive nature to try and win my office score prediction pool, I decided to quickly throw together a “fun” analysis using some of my math, programming, and most importantly, claude background.</p>

<h2 id="scoring">Scoring</h2>

<p>The league is pretty straight forward. Players make a score prediction for every game in the world cup and are scored based on the following criteria:</p>

<ol>
  <li>3 points if you predict the exact score</li>
  <li>1.5 points if you get the result right and your score is close</li>
  <li>1 point if your result is right but your score isn’t close</li>
  <li>0 points if you don’t get the result right</li>
</ol>

<p>What “your score is close” means is beyond me and I didn’t feel like checking so here we are. Also note that you can make the predictions anytime before the game starts. Anyways shoutout <a href="https://www.superbru.com/">SuperBru</a> for this prediction game and let’s get into it.</p>

<h2 id="my-approach">My Approach</h2>

<p>I aim to go for a hybrid approach of using data as well as fan intuition to make my predictions. The goal will be to create baseline predictions using available data and then develop a framework that uses added information to hopefully enhance the predictions. To keep things simple I am going to use <a href="https://help.smarkets.com/hc/en-gb/articles/214108649-What-is-1X2-betting">1X2</a> and <a href="https://www.cbssports.com/betting/news/over-under-betting/">over/under</a> betting odds for each game to base the predictions off of. Then I will use some simple historical facts/stats to create a guideline to complete my decision making for the final scores to predict.</p>

<h3 id="betting-odds">Betting Odds</h3>

<div style="display:flex; gap:1.5rem; flex-wrap:wrap; margin:1.5rem 0;">

  <div style="flex:1; min-width:220px; border:1px solid #e8e8e8; border-radius:6px; padding:1.2rem 1.4rem;">
    <p style="margin:0 0 0.5rem; font-size:0.72rem; font-weight:600; letter-spacing:0.1em; text-transform:uppercase; color:#888;">Term</p>
    <p style="margin:0 0 0.75rem; font-size:1.3rem; font-weight:600; color:#111;">1X2 Odds</p>
    <p style="margin:0; font-size:0.92rem; line-height:1.7; color:#444;">
      A three-way market where <strong>1</strong> = home win, <strong>X</strong> = draw, <strong>2</strong> = away win.
      Each outcome is priced in decimal odds, so dividing 1 by the odds to get the implied probability.
      A price of 1.65 implies a 60.6% chance.
    </p>
  </div>

  <div style="flex:1; min-width:220px; border:1px solid #e8e8e8; border-radius:6px; padding:1.2rem 1.4rem;">
    <p style="margin:0 0 0.5rem; font-size:0.72rem; font-weight:600; letter-spacing:0.1em; text-transform:uppercase; color:#888;">Term</p>
    <p style="margin:0 0 0.75rem; font-size:1.3rem; font-weight:600; color:#111;">Over / Under</p>
    <p style="margin:0; font-size:0.92rem; line-height:1.7; color:#444;">
      A market on total goals scored by both teams. The most common line is <strong>2.5</strong> —
      you bet on whether the game finishes with 3 or more goals (over) or 2 or fewer (under). Same idea as 1X2 for finding implied probability.
    </p>
  </div>

</div>

<p>I found <a href="https://the-odds-api.com/">The Odds Api</a>, which is a super cool api that gives you access to upcoming and historical sports betting odds. It has a free subscription tier where you get 500 free credits and get decent access to their data. Unfortunately, only paid members can get historical odds so I was not able to check that out, but otherwise it was easy to use and had everything I needed. Below is a simple python script showing how to extract 1X2 and over/under odds from the api. You can also check out the website above which has detailed documentation about using the API.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">requests</span>

<span class="c1">#get you key from their website when signing up and reference documenation for sport
</span><span class="n">API_KEY</span> <span class="o">=</span> <span class="s">"your_key_here"</span>
<span class="n">SPORT</span>   <span class="o">=</span> <span class="s">"soccer__fifa_world_cup"</span>  

<span class="c1">#request the correct API endpoint for odds you want
</span><span class="n">response</span> <span class="o">=</span> <span class="n">requests</span><span class="p">.</span><span class="n">get</span><span class="p">(</span>
    <span class="s">"https://api.the-odds-api.com/v4/sports/{}/odds"</span><span class="p">.</span><span class="nb">format</span><span class="p">(</span><span class="n">SPORT</span><span class="p">),</span>
    <span class="n">params</span><span class="o">=</span><span class="p">{</span>
        <span class="s">"apiKey"</span><span class="p">:</span>      <span class="n">API_KEY</span><span class="p">,</span>
        <span class="s">"regions"</span><span class="p">:</span>     <span class="s">"uk"</span><span class="p">,</span>
        <span class="s">"markets"</span><span class="p">:</span>     <span class="s">"h2h,totals"</span><span class="p">,</span>
        <span class="s">"oddsFormat"</span><span class="p">:</span>  <span class="s">"decimal"</span><span class="p">,</span>
    <span class="p">}</span>
<span class="p">)</span>

<span class="c1"># to check how many credits you have left (optional)
</span><span class="n">response</span><span class="p">.</span><span class="n">raise_for_status</span><span class="p">()</span>
    <span class="n">remaining</span> <span class="o">=</span> <span class="n">response</span><span class="p">.</span><span class="n">headers</span><span class="p">.</span><span class="n">get</span><span class="p">(</span><span class="s">"x-requests-remaining"</span><span class="p">,</span> <span class="s">"?"</span><span class="p">)</span>
    <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">"  [API] Requests remaining this month: </span><span class="si">{</span><span class="n">remaining</span><span class="si">}</span><span class="se">\n</span><span class="s">"</span><span class="p">)</span> 

<span class="c1"># get each home and away odds from the first book maker
</span><span class="k">for</span> <span class="n">match</span> <span class="ow">in</span> <span class="n">response</span><span class="p">.</span><span class="n">json</span><span class="p">():</span>
    <span class="n">home</span> <span class="o">=</span> <span class="n">match</span><span class="p">[</span><span class="s">"home_team"</span><span class="p">]</span>
    <span class="n">away</span> <span class="o">=</span> <span class="n">match</span><span class="p">[</span><span class="s">"away_team"</span><span class="p">]</span>

    <span class="k">for</span> <span class="n">bookmaker</span> <span class="ow">in</span> <span class="n">match</span><span class="p">[</span><span class="s">"bookmakers"</span><span class="p">]:</span>
        <span class="k">for</span> <span class="n">market</span> <span class="ow">in</span> <span class="n">bookmaker</span><span class="p">[</span><span class="s">"markets"</span><span class="p">]:</span>

            <span class="k">if</span> <span class="n">market</span><span class="p">[</span><span class="s">"key"</span><span class="p">]</span> <span class="o">==</span> <span class="s">"h2h"</span><span class="p">:</span>
                <span class="n">odds</span> <span class="o">=</span> <span class="p">{</span><span class="n">o</span><span class="p">[</span><span class="s">"name"</span><span class="p">]:</span> <span class="n">o</span><span class="p">[</span><span class="s">"price"</span><span class="p">]</span> <span class="k">for</span> <span class="n">o</span> <span class="ow">in</span> <span class="n">market</span><span class="p">[</span><span class="s">"outcomes"</span><span class="p">]}</span>
                <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">"</span><span class="si">{</span><span class="n">home</span><span class="si">}</span><span class="s"> vs </span><span class="si">{</span><span class="n">away</span><span class="si">}</span><span class="s">"</span><span class="p">)</span>
                <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">"  H: </span><span class="si">{</span><span class="n">odds</span><span class="p">[</span><span class="n">home</span><span class="p">]</span><span class="si">}</span><span class="s">  D: </span><span class="si">{</span><span class="n">odds</span><span class="p">[</span><span class="s">'Draw'</span><span class="p">]</span><span class="si">}</span><span class="s">  A: </span><span class="si">{</span><span class="n">odds</span><span class="p">[</span><span class="n">away</span><span class="p">]</span><span class="si">}</span><span class="s">"</span><span class="p">)</span>

            <span class="k">if</span> <span class="n">market</span><span class="p">[</span><span class="s">"key"</span><span class="p">]</span> <span class="o">==</span> <span class="s">"totals"</span><span class="p">:</span>
                <span class="k">for</span> <span class="n">o</span> <span class="ow">in</span> <span class="n">market</span><span class="p">[</span><span class="s">"outcomes"</span><span class="p">]:</span>
                    <span class="k">if</span> <span class="n">o</span><span class="p">[</span><span class="s">"name"</span><span class="p">]</span> <span class="o">==</span> <span class="s">"Over"</span><span class="p">:</span>
                        <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">"  O/U </span><span class="si">{</span><span class="n">o</span><span class="p">[</span><span class="s">'point'</span><span class="p">]</span><span class="si">}</span><span class="s">: </span><span class="si">{</span><span class="n">o</span><span class="p">[</span><span class="s">'price'</span><span class="p">]</span><span class="si">}</span><span class="s">"</span><span class="p">)</span>
        <span class="k">break</span>  <span class="c1"># first bookmaker only
</span></code></pre></div></div>
<p>My idea was that if I had the bookies odds for every team’s winning chances, as well as the line of over/under 2.5 goals in a game, then I figured I could do some sort of reverse engineering to predict each team’s winning probability and number of goals expected to score. A main theme was trying to keep the model as simple, but meaningful as possible.</p>

<h2 id="math-behind-the-model">Math Behind the Model</h2>

<p>The model uses the Poisson distribution to estimate underlying win and goal probabilites from the betting odds. The poisson distribution is a discrete probability distribution, meaning that it gives the likelihood of a countable outcome occurring <a href="https://www.scribbr.com/statistics/poisson-distribution/">(definition here)</a>. The outcome in our case is the number of goals scored in a given fixture and this value is represented by λ. The poisson distribution can be used if the following two conditions are met:</p>

<ol>
  <li>Individual events happen at random and are independent.</li>
  <li>We know the mean (average) number of events occurring within a given time interval.</li>
</ol>

<p>Number 1 is an assumption of our model. What it means is that to use the poisson distribution, goals in a soccer game must happen randomly and the impact of a goal must not affect the likelihood of who scores the next goal. In reality this is not necessarily the case as a team that concedes might push extra hard for an equalizer or blow up and concede more, however scoring in soccer is random enough to justify making this assumption.</p>

<p>Number 2 says we must know the average number of goals occurring in a game and although we do not know this, by using the over/under 2.5 goals odds, we can solve and estimate it.</p>

<hr />

<h3 id="step-1-vig-removal">Step 1: Vig Removal</h3>

<p>Just before we dive into estimating the number of goals per game, we are going to address something called <a href="https://www.legalsportsreport.com/how-to-bet/vigorish/">vigorish</a> (or vig for short). Vig is a commission added to the betting odds to ensure the bookmakers can take a profit. For a three-way market (home/draw/away) the implied probabilities, calculated as <code class="language-plaintext highlighter-rouge">1 / decimal_odds</code>, sum to more than 1. That excess is the bookmaker’s cut. Before using the odds for anything we strip it out by normalising:</p>

\[\hat{p}_i = \frac{p_i}{\sum_j p_j}\]

<p>where <code class="language-plaintext highlighter-rouge">p_i = 1 / decimal_odds_i</code> is the raw implied probability for outcome <code class="language-plaintext highlighter-rouge">i</code>, and the sum in the denominator runs over all outcomes <code class="language-plaintext highlighter-rouge">j</code> in the market. For example, odds of 1.65 / 3.80 / 5.50 produce raw probabilities that sum to 1.051. After normalisation: home 57.7%, draw 25.0%, away 17.3%.</p>

<hr />

<h3 id="step-2-solving-for-expected-goals-λ">Step 2: Solving for Expected Goals (λ)</h3>

<p>We model total goals as a Poisson random variable with unknown mean λ (the average number of goals we expect in the match). The Poisson PMF is:</p>

\[P(X = k) = \frac{\lambda^k e^{-\lambda}}{k!}\]

<p>where X is the total number of goals scored, k is a specific goal count, and e is Euler’s number. The over/under 2.5 market gives us P(goals ≥ 3) directly. We need the λ that satisfies:</p>

\[P(X \geq 3 \mid \lambda) = 1 - \sum_{k=0}^{2} \frac{\lambda^k e^{-\lambda}}{k!} = p_{\text{over}}\]

<p>where <code class="language-plaintext highlighter-rouge">p_over</code> is the normalised implied probability from the over 2.5 odds. There is no closed-form solution, so we define:</p>

\[f(\lambda) = P(X \geq 3 \mid \lambda) - p_{\text{over}} = 0\]

<p>and solve numerically using <a href="https://mathworld.wolfram.com/BrentsMethod.html">Brent’s method</a>. There is no possible way to rearrange for λ, so we have to use a numerical method like Brent’s. A market implying 55% chance of over 2.5 goals solves to λ ≈ 2.88.</p>

<hr />

<h3 id="step-3-splitting-λ-between-teams">Step 3: Splitting λ Between Teams</h3>

<p>We now have total expected goals but need to assign them to each team. We use the 1X2 win probabilities as a proxy for relative team strength, the stronger team gets a proportionally larger share:</p>

\[s = \frac{\hat{p}_{\text{home}}}{\hat{p}_{\text{home}} + \hat{p}_{\text{away}}}\]

\[\lambda_h = \lambda \cdot s \qquad \lambda_a = \lambda \cdot (1 - s)\]

<p>where s is the home team’s share of the two-outcome (home/away) probability, <code class="language-plaintext highlighter-rouge">p_home</code> and <code class="language-plaintext highlighter-rouge">p_away</code> are the normalised win probabilities from Step 1, and <code class="language-plaintext highlighter-rouge">lambda_h</code>, <code class="language-plaintext highlighter-rouge">lambda_a</code> are the resulting expected goals for the home and away team respectively. For our example: s = 0.577 / (0.577 + 0.173) = 0.769, giving λ_h = 2.21 and λ_a = 0.67.</p>

<hr />

<h3 id="known-limitations">Known Limitations</h3>

<p><strong>Draw probability is discarded in the split.</strong> The proportional split only uses win probabilities. A 25% draw probability implies the two teams’ lambdas should be close together; 10% implies they should be far apart. This information is currently unused.</p>

<p><strong>No team news or lineups.</strong> The model doesn’t know if a key player is injured or if a team is already qualified or knocked out. The market prices result probabilities but not always the scoreline distribution cleanly.</p>

<h2 id="making-the-predictions">Making the predictions</h2>

<p>The following structure will be used to make predictions:</p>
<ol>
  <li>For the first round use models predictions as is regardless of team news or injury.</li>
  <li>At the conclusion of round 1, look over injuries/team news to see if any outliers can be identified. I.e predictions under or over predicting goals.</li>
  <li>Get updated betting odds from API before the start of round 2.</li>
  <li>Use model predictions again, but adjust by a goal up or down depending on whether teams are missing key players.</li>
  <li>Same idea for final round, depending on how predictions are going two options. If good then continue with the current method, then take a look at most common score lines so far in tournament and use those for each prediction in hopes to make up some points by hitting correct scores.</li>
</ol>

<p>Below are the following predictions for each group stage game and will be updated and dated as they are played.</p>

<h3 id="group-stage-1">Group Stage 1</h3>

<p>Last updated: June 19, 2026</p>

<style>
.wc-table { width: 100%; border-collapse: collapse; font-size: 14px; }
.wc-table th { text-align: left; font-weight: 500; font-size: 11px; text-transform: uppercase; letter-spacing: 0.08em; color: #888; padding: 6px 10px; border-bottom: 1px solid #e8e8e8; }
.wc-table td { padding: 8px 10px; border-bottom: 1px solid #f0f0f0; vertical-align: middle; }
.wc-table tr:last-child td { border-bottom: none; }
.wc-table tr:hover td { background: #fafafa; }
.wc-score { font-weight: 600; font-size: 15px; font-family: monospace; white-space: nowrap; }
.wc-actual { font-family: monospace; font-size: 14px; white-space: nowrap; }
.wc-xg { font-size: 12px; color: #999; font-family: monospace; white-space: nowrap; }
.wc-date { font-size: 11px; color: #aaa; white-space: nowrap; }
.wc-hit { font-size: 11px; padding: 1px 6px; border-radius: 3px; white-space: nowrap; }
.wc-hit.exact  { background: #edf7ee; color: #2d7a35; }
.wc-hit.result { background: #fdf3e3; color: #a06010; }
.wc-hit.wrong  { background: #fdf0f0; color: #a03030; }
.wc-hit.tbd    { color: #ccc; }
</style>

<table class="wc-table">
  <thead>
    <tr>
      <th>Match</th>
      <th>Predicted</th>
      <th>xG</th>
      <th>Actual</th>
      <th></th>
    </tr>
  </thead>
  <tbody id="wc-tbody"></tbody>
</table>

<script>
(function() {
  const m = [
    ["Jun 11","Mexico","South Africa",2.08,0.34,"2-0"],
    ["Jun 12","South Korea","Czech Republic",1.25,1.14,"2-1"],
    ["Jun 12","Canada","Bosnia & Herz.",1.74,0.69,"1-1"],
    ["Jun 13","USA","Paraguay",1.62,0.75,"4-1"],
    ["Jun 13","Qatar","Switzerland",0.24,2.74,"1-1"],
    ["Jun 13","Brazil","Morocco",1.95,0.59,"1-1"],
    ["Jun 14","Haiti","Scotland",0.56,2.16,"0-1"],
    ["Jun 14","Australia","Turkey",0.64,1.93,"2-0"],
    ["Jun 14","Germany","Curaçao",4.19,0.11,"7-1"],
    ["Jun 14","Netherlands","Japan",1.70,0.94,"2-2"],
    ["Jun 14","Ivory Coast","Ecuador",0.83,1.22,"1-0"],
    ["Jun 15","Sweden","Tunisia",1.63,0.73,"5-1"],
    ["Jun 15","Spain","Cape Verde",3.46,0.15,"0-0"],
    ["Jun 15","Belgium","Egypt",2.00,0.61,"1-1"],
    ["Jun 15","Saudi Arabia","Uruguay",0.42,2.20,"1-1"],
    ["Jun 16","Iran","New Zealand",1.68,0.67,"2-2"],
    ["Jun 16","France","Senegal",2.21,0.45,"3-1"],
    ["Jun 16","Iraq","Norway",0.25,2.85,"1-4"],
    ["Jun 17","Argentina","Algeria",2.31,0.36,"3-0"],
    ["Jun 17","Austria","Jordan",2.66,0.38,"3-1"],
    ["Jun 17","Portugal","DR Congo",2.61,0.31,"1-1"],
    ["Jun 17","England","Croatia",1.86,0.66,"4-2"],
    ["Jun 17","Ghana","Panama",1.48,0.90,"1-0"],
    ["Jun 18","Uzbekistan","Colombia",0.36,2.27,"1-3"],
  ];

  function outcome(pred, actual) {
    if (!actual) return '<span class="wc-hit tbd">–</span>';
    if (pred === actual) return '<span class="wc-hit exact">exact</span>';
    const pr = pred.split('-'), ar = actual.split('-');
    const ps = Math.sign(pr[0]-pr[1]), as = Math.sign(ar[0]-ar[1]);
    return ps === as
      ? '<span class="wc-hit result">result</span>'
      : '<span class="wc-hit wrong">wrong</span>';
  }

  const tb = document.getElementById('wc-tbody');
  m.forEach(function(r) {
    const lh=r[3], la=r[4], actual=r[5];
    const pred = Math.round(lh)+'-'+Math.round(la);
    tb.innerHTML +=
      '<tr>' +
      '<td>'+r[1]+' <span style="color:#ccc">vs</span> '+r[2]+'</td>' +
      '<td class="wc-score">'+pred+'</td>' +
      '<td class="wc-xg">'+lh.toFixed(2)+' / '+la.toFixed(2)+'</td>' +
      '<td class="wc-actual">'+(actual||'–')+'</td>' +
      '<td>'+outcome(pred, actual)+'</td>' +
      '</tr>';
  });
})();
</script>

<h4 id="group-stage-1-review">Group Stage 1 Review</h4>

<p>After 24 games the model is holding up reasonably well on results (46% correct W/D/L vs 33% random baseline) but is systematically underestimating goals, missing by 0.42 per game on average.</p>

<p>The bias is largely outlier-driven — Germany 7-1, Sweden 5-1, England 4-2, and USA 4-1 account for 11 of the 23 missing goals. Strip those blowouts out and the model is close to calibrated. For competitive games it’s performing as expected.</p>

<p>The bigger pattern is a <strong>goal distribution mismatch</strong>: the model clusters predictions around 3-goal games but the tournament is running hot, with 42% of matches producing 4+ goals and 1-1 appearing six times as the most common scoreline. The model generated zero sub-2-goal predictions; in reality 4 games finished with 1 goal or fewer.</p>

<p>For matchday 2 I’ll be nudging λ upward selectively for mismatched fixtures rather than applying a global adjustment — the blowout games were all heavy favourites against weak opposition, so that’s where the model leaves the most on the table. Although 1-1 is the most common scoreline and my model rarely predicting, I am not going to adjust anything here yet and let the model run on the updated odds once again.</p>

<h3 id="group-stage-2">Group Stage 2</h3>

<p>Updated June 24</p>

<p>Only change I’ve made is a few 3-0 games bumped to 4-0. Purely based on strong teams playing weaker and the estimated xG being above 3 for the stronger team.</p>

<style>
.wc-table { width: 100%; border-collapse: collapse; font-size: 14px; }
.wc-table th { text-align: left; font-weight: 500; font-size: 11px; text-transform: uppercase; letter-spacing: 0.08em; color: #888; padding: 6px 10px; border-bottom: 1px solid #e8e8e8; }
.wc-table td { padding: 8px 10px; border-bottom: 1px solid #f0f0f0; vertical-align: middle; }
.wc-table tr:last-child td { border-bottom: none; }
.wc-table tr:hover td { background: #fafafa; }
.wc-score { font-weight: 600; font-size: 15px; font-family: monospace; white-space: nowrap; }
.wc-actual { font-family: monospace; font-size: 14px; white-space: nowrap; }
.wc-xg { font-size: 12px; color: #999; font-family: monospace; white-space: nowrap; }
.wc-date { font-size: 11px; color: #aaa; white-space: nowrap; }
.wc-hit { font-size: 11px; padding: 1px 6px; border-radius: 3px; white-space: nowrap; }
.wc-hit.exact  { background: #edf7ee; color: #2d7a35; }
.wc-hit.result { background: #fdf3e3; color: #a06010; }
.wc-hit.wrong  { background: #fdf0f0; color: #a03030; }
.wc-hit.tbd    { color: #ccc; }
</style>

<table class="wc-table">
  <thead>
    <tr>
      <th>Match</th>
      <th>Predicted</th>
      <th>xG</th>
      <th>Actual</th>
      <th></th>
    </tr>
  </thead>
  <tbody id="wc-tbody-r2"></tbody>
</table>

<script>
(function() {
  const m = [
    ["Jun 18","Czech Republic","South Africa",1.60,0.76,"1-1"],
    ["Jun 18","Switzerland","Bosnia & Herzegovina",2.01,0.55,"4-1"],
    ["Jun 18","Canada","Qatar",2.36,0.29,"6-0"],
    ["Jun 19","Mexico","South Korea",1.73,0.67,"1-0"],
    ["Jun 19","USA","Australia",1.83,0.71,"2-0"],
    ["Jun 19","Scotland","Morocco",0.76,1.58,"0-1"],
    ["Jun 20","Brazil","Haiti",3.69,0.15,"3-0"],
    ["Jun 20","Turkey","Paraguay",1.41,0.92,"0-1"],
    ["Jun 20","Netherlands","Sweden",2.02,0.64,"5-1"],
    ["Jun 20","Germany","Ivory Coast",2.17,0.60,"2-1"],
    ["Jun 21","Ecuador","Curaçao",2.74,0.24,"0-0"],
    ["Jun 21","Tunisia","Japan",0.59,1.80,"0-4"],
    ["Jun 21","Spain","Saudi Arabia",3.12,0.15,"4-0"],
    ["Jun 21","Belgium","Iran",2.30,0.40,"0-0"],
    ["Jun 21","Uruguay","Cape Verde",2.23,0.43,"2-2"],
    ["Jun 22","New Zealand","Egypt",0.63,1.77,"1-3"],
    ["Jun 22","Argentina","Austria",2.01,0.61,"2-0"],
    ["Jun 22","France","Iraq",3.12,0.15,"3-0"],
    ["Jun 23","Norway","Senegal",1.60,1.02,"3-2"],
    ["Jun 23","Jordan","Algeria",0.51,2.15,"1-2"],
    ["Jun 23","Portugal","Uzbekistan",2.87,0.32,"5-0"],
    ["Jun 23","England","Ghana",2.57,0.36,"0-0"],
    ["Jun 23","Panama","Croatia",0.50,2.07,"0-1"],
    ["Jun 24","Colombia","DR Congo",2.03,0.41,"1-0"],
  ];

  const pred = {
    "Czech Republic vs South Africa": "2-1",
    "Switzerland vs Bosnia & Herzegovina": "2-1",
    "Canada vs Qatar": "3-0",
    "Mexico vs South Korea": "2-1",
    "USA vs Australia": "2-1",
    "Scotland vs Morocco": "1-2",
    "Brazil vs Haiti": "4-0",
    "Turkey vs Paraguay": "2-1",
    "Netherlands vs Sweden": "2-1",
    "Germany vs Ivory Coast": "2-1",
    "Ecuador vs Curaçao": "3-0",
    "Tunisia vs Japan": "0-2",
    "Spain vs Saudi Arabia": "3-0",
    "Belgium vs Iran": "2-0",
    "Uruguay vs Cape Verde": "2-0",
    "New Zealand vs Egypt": "1-2",
    "Argentina vs Austria": "2-1",
    "France vs Iraq": "4-0",
    "Norway vs Senegal": "1-1",
    "Jordan vs Algeria": "1-2",
    "Portugal vs Uzbekistan": "3-0",
    "England vs Ghana": "3-0",
    "Panama vs Croatia": "0-2",
    "Colombia vs DR Congo": "2-0",
  };

  function outcome(p, actual) {
    if (!actual) return '<span class="wc-hit tbd">–</span>';
    if (p === actual) return '<span class="wc-hit exact">exact</span>';
    const pr = p.split('-'), ar = actual.split('-');
    const ps = Math.sign(pr[0]-pr[1]), as = Math.sign(ar[0]-ar[1]);
    return ps === as
      ? '<span class="wc-hit result">result</span>'
      : '<span class="wc-hit wrong">wrong</span>';
  }

  const tb = document.getElementById('wc-tbody-r2');
  m.forEach(function(r) {
    const key = r[1]+' vs '+r[2];
    const p = pred[key] || (Math.round(r[3])+'-'+Math.round(r[4]));
    const actual = r[5];
    tb.innerHTML +=
      '<tr>' +
      '<td>'+r[1]+' <span style="color:#ccc">vs</span> '+r[2]+'</td>' +
      '<td class="wc-score">'+p+'</td>' +
      '<td class="wc-xg">'+r[3].toFixed(2)+' / '+r[4].toFixed(2)+'</td>' +
      '<td class="wc-actual">'+(actual||'–')+'</td>' +
      '<td>'+outcome(p, actual||'')+'</td>' +
      '</tr>';
  });
})();
</script>

<p>After round 2, a few notes. The model has predicted 29/48 games, increasing accuracy to around 60%. I can’t be mad at this and it is probably performing a bit better than I expected. Unfortunately, my idea of bumping some 3-0 games up to 4-0 has backfired because I bumped the wrong 3-0’s up and left the ones that actually went 4-0 as 3-0. I should have probably either bumped all to 4-0 or left all at 3-0, to try and collect as many exact scores as possible.</p>

<p>Where the model has dissapointed is in exact scores. I have only got 3 exact scores so far, which means I am missing out on a lot of points. The tournament has seen nineteen 4+ goal games and I have only predicted 3. There were also a combined twelve 0 or 1 goal games where I predicted none. The model predicted thirty-one 3 goal games and only six occurred. 2 goal games were predicted fourteen times and actually happened eleven times. It clear we are predicting 3 goal games far too often and neglecting low scoring games. I think due to variance its much harder to predict high scoring games, so for round 3 we should focus our efforts on predicting more of the low-scoring outcomes.</p>

<h3 id="group-stage-3">Group Stage 3</h3>

<p>Updated June 24</p>

<p>So now what? Going into the final group stage games I have created a decision tree to help make my predictions. I will go back to the model predictions in the knockouts.</p>

<p>Are win probabilities within 20% of each other?</p>
<ul>
  <li>→ Yes: does one team have a clear incentive?</li>
  <li>
    <ul>
      <li>→ Yes: predict 1-0</li>
    </ul>
  </li>
  <li>
    <ul>
      <li>→ No: predict 0-0 or 1-1, whichever’s closer to prediction.</li>
    </ul>
  </li>
  <li>→ No (clear favourite): Does model predict 3-0 or higher?</li>
  <li>
    <ul>
      <li>→ Yes: drop to 2-0</li>
    </ul>
  </li>
  <li>
    <ul>
      <li>→ No: drop predicted goals by 1 (2-1 → 1-0, 2-0 → 1-0)</li>
    </ul>
  </li>
</ul>

<p>With this set of logic the idea is to target the low-scoring games we have missed out on thus far. Given the final round I think a lot of teams will be set up very defensively with their tournaments on the line so I don’t see why low-scoring shouldn’t continue to happen. With that being said here are my picks:</p>

<style>
.wc-table { width: 100%; border-collapse: collapse; font-size: 14px; }
.wc-table th { text-align: left; font-weight: 500; font-size: 11px; text-transform: uppercase; letter-spacing: 0.08em; color: #888; padding: 6px 10px; border-bottom: 1px solid #e8e8e8; }
.wc-table td { padding: 8px 10px; border-bottom: 1px solid #f0f0f0; vertical-align: middle; }
.wc-table tr:last-child td { border-bottom: none; }
.wc-table tr:hover td { background: #fafafa; }
.wc-score { font-weight: 600; font-size: 15px; font-family: monospace; white-space: nowrap; }
.wc-actual { font-family: monospace; font-size: 14px; white-space: nowrap; }
.wc-xg { font-size: 12px; color: #999; font-family: monospace; white-space: nowrap; }
.wc-date { font-size: 11px; color: #aaa; white-space: nowrap; }
.wc-hit { font-size: 11px; padding: 1px 6px; border-radius: 3px; white-space: nowrap; }
.wc-hit.exact  { background: #edf7ee; color: #2d7a35; }
.wc-hit.result { background: #fdf3e3; color: #a06010; }
.wc-hit.wrong  { background: #fdf0f0; color: #a03030; }
.wc-hit.tbd    { color: #ccc; }
</style>

<table class="wc-table">
  <thead>
    <tr>
      <th>Match</th>
      <th>Predicted</th>
      <th>xG</th>
      <th>Actual</th>
      <th></th>
    </tr>
  </thead>
  <tbody id="wc-tbody-r3"></tbody>
</table>

<script>
(function() {
  const m = [
    ["Jun 24","Bosnia & Herzegovina","Qatar",2.65,0.47,"3-1"],
    ["Jun 24","Switzerland","Canada",1.44,1.05,"2-1"],
    ["Jun 24","Scotland","Brazil",0.33,2.47,"0-3"],
    ["Jun 24","Morocco","Haiti",2.94,0.21,"4-2"],
    ["Jun 25","Czech Republic","Mexico",0.87,1.71,"0-3"],
    ["Jun 25","South Africa","South Korea",0.57,2.00,"1-0"],
    ["Jun 25","Curaçao","Ivory Coast",0.20,3.05,"0-2"],
    ["Jun 25","Ecuador","Germany",0.93,1.93,"2-1"],
    ["Jun 25","Japan","Sweden",2.00,0.87,"1-1"],
    ["Jun 25","Tunisia","Netherlands",0.16,3.17,"1-3"],
    ["Jun 26","Paraguay","Australia",1.14,0.84,"0-0"],
    ["Jun 26","Turkey","USA",1.01,1.89,"3-2"],
    ["Jun 26","Norway","France",0.78,2.18,"1-4"],
    ["Jun 26","Senegal","Iraq",2.93,0.29,"5-0"],
    ["Jun 27","Cape Verde","Saudi Arabia",1.39,1.17,"0-0"],
    ["Jun 27","Uruguay","Spain",0.49,2.23,"0-1"],
    ["Jun 27","New Zealand","Belgium",0.23,2.95,"1-5"],
    ["Jun 27","Egypt","Iran",1.26,0.84,"1-1"],
    ["Jun 27","Croatia","Ghana",1.81,0.58,"2-1"],
    ["Jun 27","Panama","England",0.24,3.13,"0-2"],
    ["Jun 27","Colombia","Portugal",0.82,1.73,"0-0"],
    ["Jun 27","DR Congo","Uzbekistan",1.87,0.81,"3-1"],
    ["Jun 28","Algeria","Austria",0.89,1.22,"3-3"],
    ["Jun 28","Jordan","Argentina",0.24,2.86,"1-3"],
  ];

  const pred = {
    "Bosnia & Herzegovina vs Qatar": "2-0",
    "Switzerland vs Canada": "1-1",
    "Scotland vs Brazil": "0-1",
    "Morocco vs Haiti": "2-0",
    "Czech Republic vs Mexico": "0-1",
    "South Africa vs South Korea": "0-1",
    "Curaçao vs Ivory Coast": "0-2",
    "Ecuador vs Germany": "0-1",
    "Japan vs Sweden": "1-0",
    "Tunisia vs Netherlands": "0-2",
    "Paraguay vs Australia": "1-1",
    "Turkey vs USA": "0-1",
    "Norway vs France": "0-1",
    "Senegal vs Iraq": "2-0",
    "Cape Verde vs Saudi Arabia": "1-1",
    "Uruguay vs Spain": "0-1",
    "New Zealand vs Belgium": "0-2",
    "Egypt vs Iran": "0-1",
    "Croatia vs Ghana": "1-0",
    "Panama vs England": "0-2",
    "Colombia vs Portugal": "0-1",
    "DR Congo vs Uzbekistan": "1-0",
    "Algeria vs Austria": "1-1",
    "Jordan vs Argentina": "0-2",
  };

  function outcome(p, actual) {
    if (!actual) return '<span class="wc-hit tbd">–</span>';
    if (p === actual) return '<span class="wc-hit exact">exact</span>';
    const pr = p.split('-'), ar = actual.split('-');
    const ps = Math.sign(pr[0]-pr[1]), as = Math.sign(ar[0]-ar[1]);
    return ps === as
      ? '<span class="wc-hit result">result</span>'
      : '<span class="wc-hit wrong">wrong</span>';
  }

  const tb = document.getElementById('wc-tbody-r3');
  m.forEach(function(r) {
    const key = r[1]+' vs '+r[2];
    const p = pred[key] || (Math.round(r[3])+'-'+Math.round(r[4]));
    const actual = r[5];
    tb.innerHTML +=
      '<tr>' +
      '<td>'+r[1]+' <span style="color:#ccc">vs</span> '+r[2]+'</td>' +
      '<td class="wc-score">'+p+'</td>' +
      '<td class="wc-xg">'+r[3].toFixed(2)+' / '+r[4].toFixed(2)+'</td>' +
      '<td class="wc-actual">'+(actual||'–')+'</td>' +
      '<td>'+outcome(p, actual||'')+'</td>' +
      '</tr>';
  });
})();
</script>

<h3 id="round-of-32">Round of 32</h3>

<p>Updated June 29</p>

<p>Round of 32 up next. I ended up going 17/24 correct outcomes with 3 exact last round. The method of predicting low scoring, got us a good return but not much different that the model in round 2. Because of this and the fact that knockouts begin, I am going to go back to using the model predictions as is. We will reassess after the round of 32. In the league I am playing in I currently in 67/411. So not great but not terrible either. Last round shot us up a bunch so hopefully we will conintue to climb. Anyways here are my predictions.</p>

<style>
.wc-table { width: 100%; border-collapse: collapse; font-size: 14px; }
.wc-table th { text-align: left; font-weight: 500; font-size: 11px; text-transform: uppercase; letter-spacing: 0.08em; color: #888; padding: 6px 10px; border-bottom: 1px solid #e8e8e8; }
.wc-table td { padding: 8px 10px; border-bottom: 1px solid #f0f0f0; vertical-align: middle; }
.wc-table tr:last-child td { border-bottom: none; }
.wc-table tr:hover td { background: #fafafa; }
.wc-score { font-weight: 600; font-size: 15px; font-family: monospace; white-space: nowrap; }
.wc-actual { font-family: monospace; font-size: 14px; white-space: nowrap; }
.wc-xg { font-size: 12px; color: #999; font-family: monospace; white-space: nowrap; }
.wc-date { font-size: 11px; color: #aaa; white-space: nowrap; }
.wc-hit { font-size: 11px; padding: 1px 6px; border-radius: 3px; white-space: nowrap; }
.wc-hit.exact  { background: #edf7ee; color: #2d7a35; }
.wc-hit.result { background: #fdf3e3; color: #a06010; }
.wc-hit.wrong  { background: #fdf0f0; color: #a03030; }
.wc-hit.tbd    { color: #ccc; }
</style>

<table class="wc-table">
  <thead>
    <tr>
      <th>Match</th>
      <th>Predicted</th>
      <th>xG</th>
      <th>Actual</th>
      <th></th>
    </tr>
  </thead>
  <tbody id="wc-tbody-r16"></tbody>
</table>

<script>
(function() {
  const m = [
    ["Jun 28","South Africa","Canada",0.54,1.85,"1-2"],
    ["Jun 29","Brazil","Japan",1.98,0.65,"2-1"],
    ["Jun 29","Germany","Paraguay",2.58,0.35,"1-1"],
    ["Jun 30","Netherlands","Morocco",1.52,0.91,"1-1"],
    ["Jun 30","Ivory Coast","Norway",0.96,1.76,"1-2"],
    ["Jun 30","France","Sweden",2.91,0.33,"3-0"],
    ["Jul 1","Mexico","Ecuador",1.30,0.78,"2-0"],
    ["Jul 1","England","DR Congo",2.50,0.24,"2-1"],
    ["Jul 1","Belgium","Senegal",1.47,0.87,"3-2"],
    ["Jul 2","USA","Bosnia & Herzegovina",2.43,0.36,"2-0"],
    ["Jul 2","Spain","Austria",2.42,0.26,"3-0"],
    ["Jul 2","Portugal","Croatia",1.77,0.67,"2-1"],
    ["Jul 3","Switzerland","Algeria",1.79,0.78,"2-0"],
    ["Jul 3","Australia","Egypt",0.89,1.19,"1-1"],
    ["Jul 3","Argentina","Cape Verde",2.91,0.17,"3-2"],
    ["Jul 4","Colombia","Ghana",1.92,0.45,"1-0"],
  ];

  function outcome(p, actual) {
    if (!actual) return '<span class="wc-hit tbd">–</span>';
    if (p === actual) return '<span class="wc-hit exact">exact</span>';
    const pr = p.split('-'), ar = actual.split('-');
    const ps = Math.sign(pr[0]-pr[1]), as = Math.sign(ar[0]-ar[1]);
    return ps === as
      ? '<span class="wc-hit result">result</span>'
      : '<span class="wc-hit wrong">wrong</span>';
  }

  const tb = document.getElementById('wc-tbody-r16');
  m.forEach(function(r) {
    const p = Math.round(r[3])+'-'+Math.round(r[4]);
    const actual = r[5];
    tb.innerHTML +=
      '<tr>' +
      '<td>'+r[1]+' <span style="color:#ccc">vs</span> '+r[2]+'</td>' +
      '<td class="wc-score">'+p+'</td>' +
      '<td class="wc-xg">'+r[3].toFixed(2)+' / '+r[4].toFixed(2)+'</td>' +
      '<td class="wc-actual">'+(actual||'–')+'</td>' +
      '<td>'+outcome(p, actual||'')+'</td>' +
      '</tr>';
  });
})();
</script>

<p>We continue to climb getting up to around 30th in my office pool. Best round yet with 68% accuracy and 37.5% exact scorelines. I’ll chalk it up that we were just due for some good fortune, but we will leave the model as is going into the next round and see how it holds.</p>

<h3 id="round-of-16">Round of 16</h3>

<p>Updated July 4</p>

<p>Nothing new here, model predictions are as follows:</p>

<style>
.wc-table { width: 100%; border-collapse: collapse; font-size: 14px; }
.wc-table th { text-align: left; font-weight: 500; font-size: 11px; text-transform: uppercase; letter-spacing: 0.08em; color: #888; padding: 6px 10px; border-bottom: 1px solid #e8e8e8; }
.wc-table td { padding: 8px 10px; border-bottom: 1px solid #f0f0f0; vertical-align: middle; }
.wc-table tr:last-child td { border-bottom: none; }
.wc-table tr:hover td { background: #fafafa; }
.wc-score { font-weight: 600; font-size: 15px; font-family: monospace; white-space: nowrap; }
.wc-actual { font-family: monospace; font-size: 14px; white-space: nowrap; }
.wc-xg { font-size: 12px; color: #999; font-family: monospace; white-space: nowrap; }
.wc-date { font-size: 11px; color: #aaa; white-space: nowrap; }
.wc-hit { font-size: 11px; padding: 1px 6px; border-radius: 3px; white-space: nowrap; }
.wc-hit.exact  { background: #edf7ee; color: #2d7a35; }
.wc-hit.result { background: #fdf3e3; color: #a06010; }
.wc-hit.wrong  { background: #fdf0f0; color: #a03030; }
.wc-hit.tbd    { color: #ccc; }
</style>

<table class="wc-table">
  <thead>
    <tr>
      <th>Match</th>
      <th>Predicted</th>
      <th>xG</th>
      <th>Actual</th>
      <th></th>
    </tr>
  </thead>
  <tbody id="wc-tbody-r16b"></tbody>
</table>

<script>
(function() {
  const m = [
    ["Jul 4","Canada","Morocco",0.68,1.72,"0-3"],
    ["Jul 4","Paraguay","France",0.18,2.80,"0-1"],
    ["Jul 5","Brazil","Norway",2.02,0.85,"1-2"],
    ["Jul 6","Mexico","England",1.00,1.27,"2-3"],
    ["Jul 6","Portugal","Spain",0.86,1.84,"0-1"],
    ["Jul 7","USA","Belgium",1.37,1.47,"1-4"],
    ["Jul 7","Argentina","Egypt",2.26,0.32,"3-2"],
    ["Jul 7","Switzerland","Colombia",0.92,1.43,"0-0"],
  ];

  const pred = {
    "Canada vs Morocco": "1-2",
    "Paraguay vs France": "0-3",
    "Brazil vs Norway": "2-1",
    "Mexico vs England": "1-1",
    "Portugal vs Spain": "1-2",
    "USA vs Belgium": "1-1",
    "Argentina vs Egypt": "2-0",
    "Switzerland vs Colombia": "1-1",
  };

  function outcome(p, actual) {
    if (!actual) return '<span class="wc-hit tbd">–</span>';
    if (p === actual) return '<span class="wc-hit exact">exact</span>';
    const pr = p.split('-'), ar = actual.split('-');
    const ps = Math.sign(pr[0]-pr[1]), as = Math.sign(ar[0]-ar[1]);
    return ps === as
      ? '<span class="wc-hit result">result</span>'
      : '<span class="wc-hit wrong">wrong</span>';
  }

  const tb = document.getElementById('wc-tbody-r16b');
  m.forEach(function(r) {
    const key = r[1]+' vs '+r[2];
    const p = pred[key] || (Math.round(r[3])+'-'+Math.round(r[4]));
    const actual = r[5];
    tb.innerHTML +=
      '<tr>' +
      '<td>'+r[1]+' <span style="color:#ccc">vs</span> '+r[2]+'</td>' +
      '<td class="wc-score">'+p+'</td>' +
      '<td class="wc-xg">'+r[3].toFixed(2)+' / '+r[4].toFixed(2)+'</td>' +
      '<td class="wc-actual">'+(actual||'–')+'</td>' +
      '<td>'+outcome(p, actual||'')+'</td>' +
      '</tr>';
  });
})();
</script>

<h3 id="quarter-finals">Quarter Finals</h3>

<p>Updated July 9</p>

<p>No exact scores for the round of 16. The model had England and Belgium tying which personally I would’ve picked wins for both, but other than that some pretty unpredictable scorelines.</p>

<p>The most common scorelines are 1-0 with 14, 1-1 with 12, 2-1 with 11, 2-0 with 9, and 0-0 with 8. The model has the favorites winning 2-1 in every game of the quarterfinals. Although personally I would go with 1-0 for some games given it’s late in the world cup and teams will probably tend to start favoring defense, I think picking the same score for every match gives me a good chance of getting exact scores, especially since 2-1 is common. Part of me wants to go 1-0 for each, but I will put some faith in the model and let it try and prove itself once again.</p>

<style>
.wc-table { width: 100%; border-collapse: collapse; font-size: 14px; }
.wc-table th { text-align: left; font-weight: 500; font-size: 11px; text-transform: uppercase; letter-spacing: 0.08em; color: #888; padding: 6px 10px; border-bottom: 1px solid #e8e8e8; }
.wc-table td { padding: 8px 10px; border-bottom: 1px solid #f0f0f0; vertical-align: middle; }
.wc-table tr:last-child td { border-bottom: none; }
.wc-table tr:hover td { background: #fafafa; }
.wc-score { font-weight: 600; font-size: 15px; font-family: monospace; white-space: nowrap; }
.wc-actual { font-family: monospace; font-size: 14px; white-space: nowrap; }
.wc-xg { font-size: 12px; color: #999; font-family: monospace; white-space: nowrap; }
.wc-date { font-size: 11px; color: #aaa; white-space: nowrap; }
.wc-hit { font-size: 11px; padding: 1px 6px; border-radius: 3px; white-space: nowrap; }
.wc-hit.exact  { background: #edf7ee; color: #2d7a35; }
.wc-hit.result { background: #fdf3e3; color: #a06010; }
.wc-hit.wrong  { background: #fdf0f0; color: #a03030; }
.wc-hit.tbd    { color: #ccc; }
</style>

<table class="wc-table">
  <thead>
    <tr>
      <th>Match</th>
      <th>Predicted</th>
      <th>xG</th>
      <th>Actual</th>
      <th></th>
    </tr>
  </thead>
  <tbody id="wc-tbody-qf"></tbody>
</table>

<script>
(function() {
  const m = [
    ["Jul 9","France","Morocco",2.06,0.51,"2-0"],
    ["Jul 10","Spain","Belgium",2.17,0.65,"2-1"],
    ["Jul 11","Norway","England",0.88,1.98,"1-2"],
    ["Jul 12","Argentina","Switzerland",1.83,0.56,"3-1"],
  ];

  const pred = {
    "France vs Morocco": "2-1",
    "Spain vs Belgium": "2-1",
    "Norway vs England": "1-2",
    "Argentina vs Switzerland": "2-1",
  };

  function outcome(p, actual) {
    if (!actual) return '<span class="wc-hit tbd">–</span>';
    if (p === actual) return '<span class="wc-hit exact">exact</span>';
    const pr = p.split('-'), ar = actual.split('-');
    const ps = Math.sign(pr[0]-pr[1]), as = Math.sign(ar[0]-ar[1]);
    return ps === as
      ? '<span class="wc-hit result">result</span>'
      : '<span class="wc-hit wrong">wrong</span>';
  }

  const tb = document.getElementById('wc-tbody-qf');
  m.forEach(function(r) {
    const key = r[1]+' vs '+r[2];
    const p = pred[key] || (Math.round(r[3])+'-'+Math.round(r[4]));
    const actual = r[5];
    tb.innerHTML +=
      '<tr>' +
      '<td>'+r[1]+' <span style="color:#ccc">vs</span> '+r[2]+'</td>' +
      '<td class="wc-score">'+p+'</td>' +
      '<td class="wc-xg">'+r[3].toFixed(2)+' / '+r[4].toFixed(2)+'</td>' +
      '<td class="wc-actual">'+(actual||'–')+'</td>' +
      '<td>'+outcome(p, actual||'')+'</td>' +
      '</tr>';
  });
})();
</script>

<h3 id="semi-finals">Semi Finals</h3>

<p>Updated July 12</p>

<p>Not bad quarter finals. 2 exact and 2 close. I am currently sitting around 30th out of 250 in the office league. Trusting the model paid off, I think picking the same score for every game at this point is a good strategy. However, I will still follow the model for the semis. Both are close games and I think the only way to really make up any serious ground is to get exact for both.</p>

<table class="wc-table">
  <thead>
    <tr>
      <th>Match</th>
      <th>Predicted</th>
      <th>xG</th>
      <th>Actual</th>
      <th></th>
    </tr>
  </thead>
  <tbody id="wc-tbody-sf"></tbody>
</table>

<script>
(function() {
  const m = [
    ["France","Spain",1.56,1.12,"0-2"],
    ["England","Argentina",1.26,1.07,"1-2"],
  ];

  const pred = {
    "France vs Spain": "2-1",
    "England vs Argentina": "1-1",
  };

  function outcome(p, actual) {
    if (!actual) return '<span class="wc-hit tbd">–</span>';
    if (p === actual) return '<span class="wc-hit exact">exact</span>';
    const pr = p.split('-'), ar = actual.split('-');
    const ps = Math.sign(pr[0]-pr[1]), as = Math.sign(ar[0]-ar[1]);
    return ps === as
      ? '<span class="wc-hit result">result</span>'
      : '<span class="wc-hit wrong">wrong</span>';
  }

  const tb = document.getElementById('wc-tbody-sf');
  m.forEach(function(r) {
    const key = r[0]+' vs '+r[1];
    const p = pred[key] || (Math.round(r[2])+'-'+Math.round(r[3]));
    const actual = r[4];
    tb.innerHTML +=
      '<tr>' +
      '<td>'+r[0]+' <span style="color:#ccc">vs</span> '+r[1]+'</td>' +
      '<td class="wc-score">'+p+'</td>' +
      '<td class="wc-xg">'+r[2].toFixed(2)+' / '+r[3].toFixed(2)+'</td>' +
      '<td class="wc-actual">'+(actual||'–')+'</td>' +
      '<td>'+outcome(p, actual||'')+'</td>' +
      '</tr>';
  });
})();
</script>

<h2 id="final">Final</h2>

<p>Updated July 20</p>

<p>Was slacking a bit and forgot to update. Previous round was rough, as neither of the bookies favorites made the final. Not much I think can be done at this stage as there’s only 2 games and the team’s are so close we shall just let it play out.</p>

<table class="wc-table">
  <thead>
    <tr>
      <th>Match</th>
      <th>Predicted</th>
      <th>xG</th>
      <th>Actual</th>
      <th></th>
    </tr>
  </thead>
  <tbody id="wc-tbody-f"></tbody>
</table>

<script>
(function() {
  const m = [
    ["France","England",2.32,1.09,"4-6"],
    ["Spain","Argentina",1.44,0.92,"1-0"],
  ];

  const pred = {
    "France vs England": "3-2",
    "England vs Argentina": "1-1",
  };

  function outcome(p, actual) {
    if (!actual) return '<span class="wc-hit tbd">–</span>';
    if (p === actual) return '<span class="wc-hit exact">exact</span>';
    const pr = p.split('-'), ar = actual.split('-');
    const ps = Math.sign(pr[0]-pr[1]), as = Math.sign(ar[0]-ar[1]);
    return ps === as
      ? '<span class="wc-hit result">result</span>'
      : '<span class="wc-hit wrong">wrong</span>';
  }

  const tb = document.getElementById('wc-tbody-f');
  m.forEach(function(r) {
    const key = r[0]+' vs '+r[1];
    const p = pred[key] || (Math.round(r[2])+'-'+Math.round(r[3]));
    const actual = r[4];
    tb.innerHTML +=
      '<tr>' +
      '<td>'+r[0]+' <span style="color:#ccc">vs</span> '+r[1]+'</td>' +
      '<td class="wc-score">'+p+'</td>' +
      '<td class="wc-xg">'+r[2].toFixed(2)+' / '+r[3].toFixed(2)+'</td>' +
      '<td class="wc-actual">'+(actual||'–')+'</td>' +
      '<td>'+outcome(p, actual||'')+'</td>' +
      '</tr>';
  });
})();
</script>

<p>I increased the England France scoring predictions from 2-1 France, to 3-2, as I figured the third place match would be high scoring, but truly the unthinkable happened haha. Also pure domination from Spain and I had them myself down as 1-0 win but obviously took the models prediction.</p>

<h2 id="wrap-up">Wrap Up</h2>

<p>Updated June 12, 2026</p>

<p>I don’t have much to say right now other than GO CANADA, and hopefully these predictions can serve me well. I will at the least update this post at the end of every groupstage round, but hopefully more often than that. Anyways I appreciate those who made it this far and best of luck to you and your team you will be cheering on this World Cup!</p>

<p>Updated July 20, 2026</p>

<p>Well the world cup is finished, congrats to Spain, and every other team that created history and special moments for their countries.</p>

<p>I ended up finishing 42/408 in my office league, narrowly missing the top 10%. 104 games predicted, 21 results correct, 30 close scores, and 14 exact scores. A prediction success rate of 63%. A few takeaways/lessons/ideas to learn from and hopefully improve upon next time.</p>

<ul>
  <li>Use a method of comparison. I should have made my predictions for each game as an avid football fan, seeing how my predictions would have stacked up vs the model.</li>
  <li>Compare the results of the model to other common approaches. Does this model actually meaningfully improve predictions, or would I have had better success predicting the most common scoreline historically for every game?</li>
  <li>In a game scenario like this office pool, are there oppurtunites to sytematically hedge my prediction to try and make ground? I.e if the model had two teams with relatively close odds, and one team was heavily being chosen to win more than the other, picking the less common choice may statistically have given me advantage.</li>
</ul>

<p>Overall, this was a fun experience and I am glad I did it. Although I know it was not thourougly thought through or planned, it is nice to have seen it through from start to end, and more importantly it has piqued my interest in continuing to do more predictions and learning how to improve them. Thanks for following along!</p>

<p>Jack Sears</p>]]></content><author><name></name></author><category term="notes" /><summary type="html"><![CDATA[]]></summary></entry></feed>